> For the complete documentation index, see [llms.txt](https://boinc-ai.gitbook.io/transformers/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://boinc-ai.gitbook.io/transformers/api/models/text-models/markuplm.md).
# MarkupLM
## MarkupLM
### Overview
The MarkupLM model was proposed in [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei. MarkupLM is BERT, but applied to HTML pages instead of raw text documents. The model incorporates additional embedding layers to improve performance, similar to [LayoutLM](https://huggingface.co/docs/transformers/model_doc/layoutlm).
The model can be used for tasks like question answering on web pages or information extraction from web pages. It obtains state-of-the-art results on 2 important benchmarks:
* [WebSRC](https://x-lance.github.io/WebSRC/), a dataset for Web-Based Structural Reading Comprehension (a bit like SQuAD but for web pages)
* [SWDE](https://www.researchgate.net/publication/221299838_From_one_tree_to_a_forest_a_unified_solution_for_structured_web_data_extraction), a dataset for information extraction from web pages (basically named-entity recogntion on web pages)
The abstract from the paper is the following:
*Multimodal pre-training with text, layout, and image has made significant progress for Visually-rich Document Understanding (VrDU), especially the fixed-layout documents such as scanned document images. While, there are still a large number of digital documents where the layout information is not fixed and needs to be interactively and dynamically rendered for visualization, making existing layout-based pre-training approaches not easy to apply. In this paper, we propose MarkupLM for document understanding tasks with markup languages as the backbone such as HTML/XML-based documents, where text and markup information is jointly pre-trained. Experiment results show that the pre-trained MarkupLM significantly outperforms the existing strong baseline models on several document understanding tasks. The pre-trained model and code will be publicly available.*
Tips:
* In addition to `input_ids`, [forward()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMModel.forward) expects 2 additional inputs, namely `xpath_tags_seq` and `xpath_subs_seq`. These are the XPATH tags and subscripts respectively for each token in the input sequence.
* One can use [MarkupLMProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMProcessor) to prepare all data for the model. Refer to the [usage guide](https://huggingface.co/docs/transformers/model_doc/markuplm#usage-markuplmprocessor) for more info.
* Demo notebooks can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/MarkupLM).
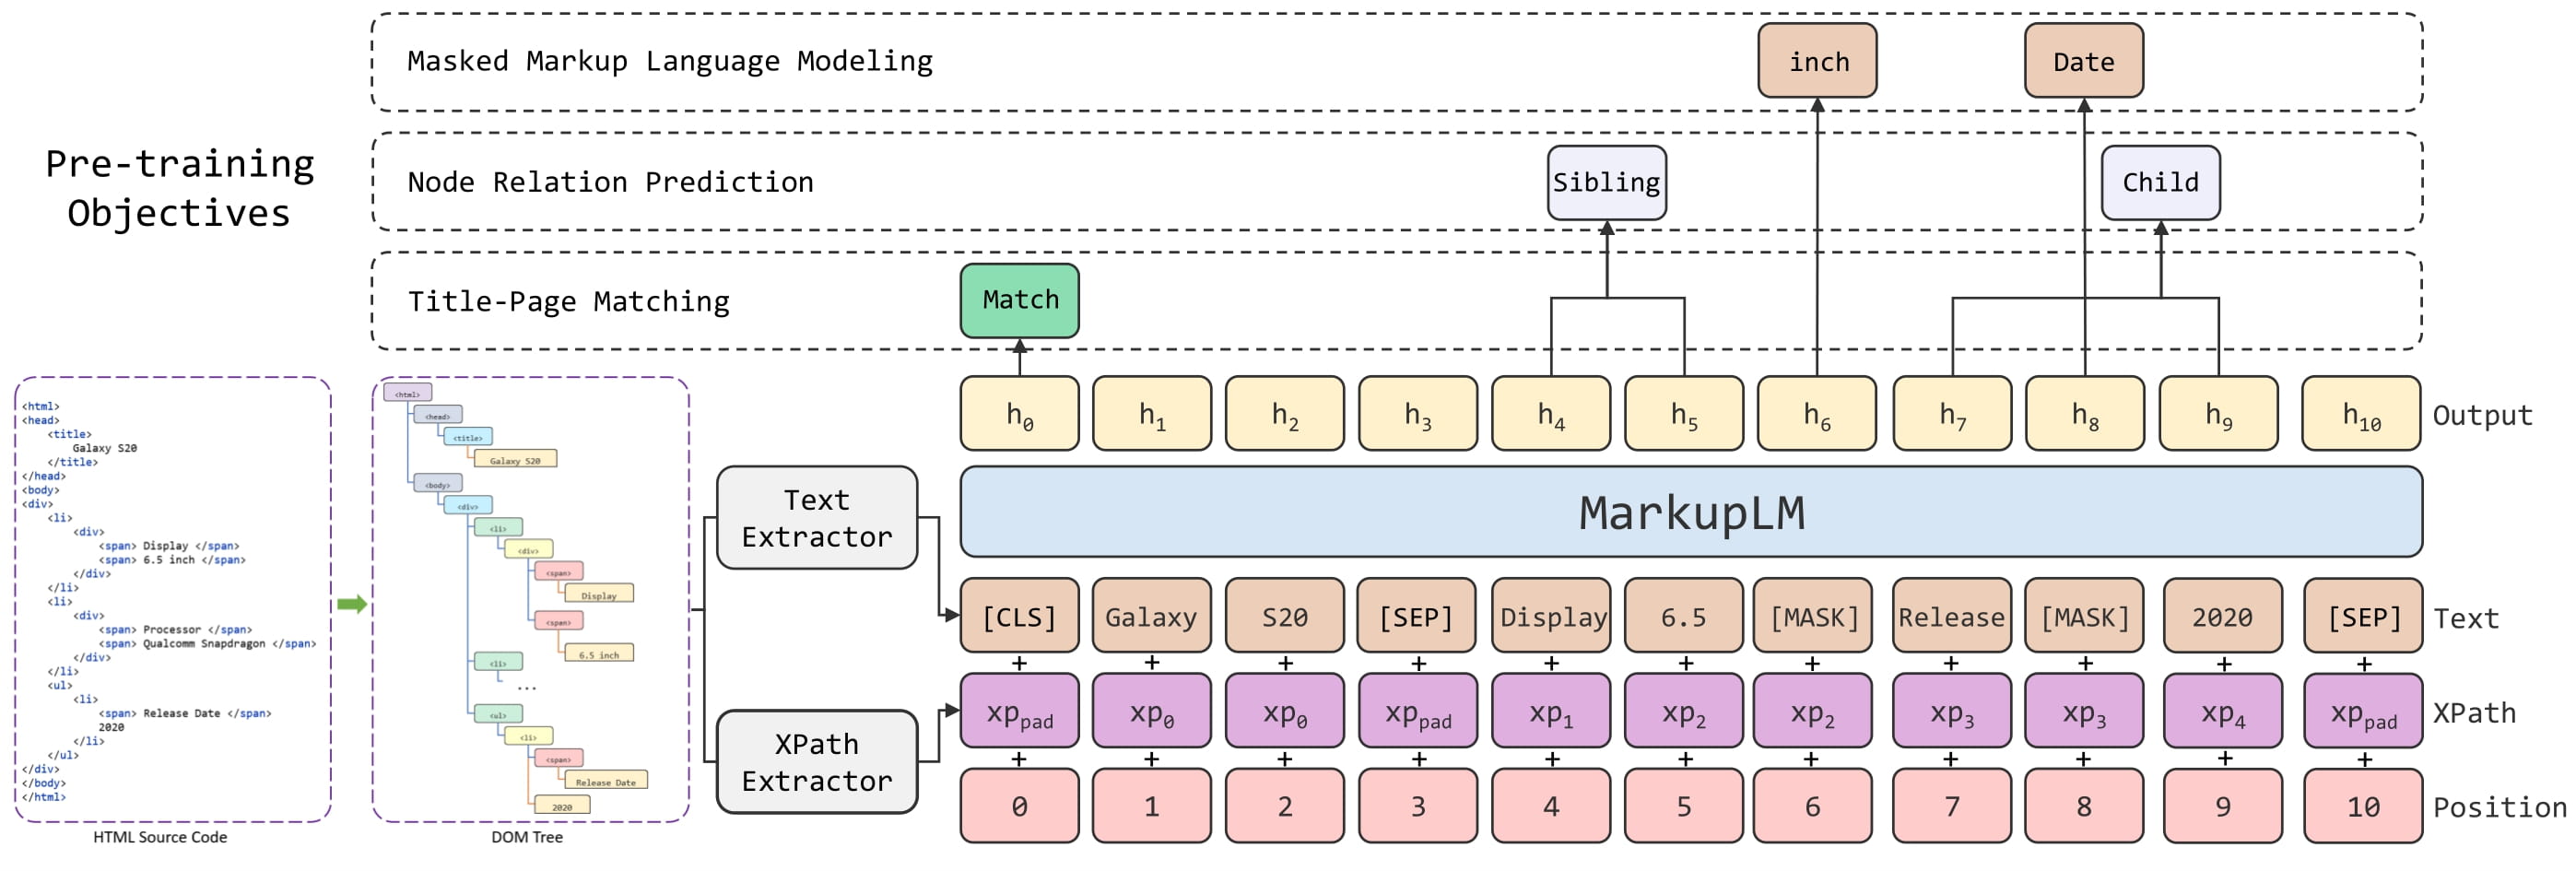MarkupLM architecture. Taken from the [original paper.](https://arxiv.org/abs/2110.08518)
This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/markuplm).
### Usage: MarkupLMProcessor
The easiest way to prepare data for the model is to use [MarkupLMProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMProcessor), which internally combines a feature extractor ([MarkupLMFeatureExtractor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor)) and a tokenizer ([MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) or [MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast)). The feature extractor is used to extract all nodes and xpaths from the HTML strings, which are then provided to the tokenizer, which turns them into the token-level inputs of the model (`input_ids` etc.). Note that you can still use the feature extractor and tokenizer separately, if you only want to handle one of the two tasks.
Copied
```
from transformers import MarkupLMFeatureExtractor, MarkupLMTokenizerFast, MarkupLMProcessor
feature_extractor = MarkupLMFeatureExtractor()
tokenizer = MarkupLMTokenizerFast.from_pretrained("microsoft/markuplm-base")
processor = MarkupLMProcessor(feature_extractor, tokenizer)
```
In short, one can provide HTML strings (and possibly additional data) to [MarkupLMProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMProcessor), and it will create the inputs expected by the model. Internally, the processor first uses [MarkupLMFeatureExtractor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor) to get a list of nodes and corresponding xpaths. The nodes and xpaths are then provided to [MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) or [MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast), which converts them to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_subs_seq`, `xpath_tags_seq`. Optionally, one can provide node labels to the processor, which are turned into token-level `labels`.
[MarkupLMFeatureExtractor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor) uses [Beautiful Soup](https://www.crummy.com/software/BeautifulSoup/bs4/doc/), a Python library for pulling data out of HTML and XML files, under the hood. Note that you can still use your own parsing solution of choice, and provide the nodes and xpaths yourself to [MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) or [MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast).
In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
**Use case 1: web page classification (training, inference) + token classification (inference), parse\_html = True**
This is the simplest case, in which the processor will use the feature extractor to get all nodes and xpaths from the HTML.
Copied
```
>>> from transformers import MarkupLMProcessor
>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
>>> html_string = """
...
...
...
... Hello world
...
...
...
Welcome
...
Here is my website.
...
... """
>>> # note that you can also add provide all tokenizer parameters here such as padding, truncation
>>> encoding = processor(html_string, return_tensors="pt")
>>> print(encoding.keys())
dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
```
**Use case 2: web page classification (training, inference) + token classification (inference), parse\_html=False**
In case one already has obtained all nodes and xpaths, one doesn’t need the feature extractor. In that case, one should provide the nodes and corresponding xpaths themselves to the processor, and make sure to set `parse_html` to `False`.
Copied
```
>>> from transformers import MarkupLMProcessor
>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
>>> processor.parse_html = False
>>> nodes = ["hello", "world", "how", "are"]
>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
>>> encoding = processor(nodes=nodes, xpaths=xpaths, return_tensors="pt")
>>> print(encoding.keys())
dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
```
**Use case 3: token classification (training), parse\_html=False**
For token classification tasks (such as [SWDE](https://paperswithcode.com/dataset/swde)), one can also provide the corresponding node labels in order to train a model. The processor will then convert these into token-level `labels`. By default, it will only label the first wordpiece of a word, and label the remaining wordpieces with -100, which is the `ignore_index` of PyTorch’s CrossEntropyLoss. In case you want all wordpieces of a word to be labeled, you can initialize the tokenizer with `only_label_first_subword` set to `False`.
Copied
```
>>> from transformers import MarkupLMProcessor
>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
>>> processor.parse_html = False
>>> nodes = ["hello", "world", "how", "are"]
>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
>>> node_labels = [1, 2, 2, 1]
>>> encoding = processor(nodes=nodes, xpaths=xpaths, node_labels=node_labels, return_tensors="pt")
>>> print(encoding.keys())
dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq', 'labels'])
```
**Use case 4: web page question answering (inference), parse\_html=True**
For question answering tasks on web pages, you can provide a question to the processor. By default, the processor will use the feature extractor to get all nodes and xpaths, and create \[CLS] question tokens \[SEP] word tokens \[SEP].
Copied
```
>>> from transformers import MarkupLMProcessor
>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
>>> html_string = """
...
...
...
... Hello world
...
...
...
Welcome
...
My name is Niels.
...
... """
>>> question = "What's his name?"
>>> encoding = processor(html_string, questions=question, return_tensors="pt")
>>> print(encoding.keys())
dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
```
**Use case 5: web page question answering (inference), parse\_html=False**
For question answering tasks (such as WebSRC), you can provide a question to the processor. If you have extracted all nodes and xpaths yourself, you can provide them directly to the processor. Make sure to set `parse_html` to `False`.
Copied
```
>>> from transformers import MarkupLMProcessor
>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
>>> processor.parse_html = False
>>> nodes = ["hello", "world", "how", "are"]
>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
>>> question = "What's his name?"
>>> encoding = processor(nodes=nodes, xpaths=xpaths, questions=question, return_tensors="pt")
>>> print(encoding.keys())
dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
```
### Documentation resources
* [Text classification task guide](https://huggingface.co/docs/transformers/tasks/sequence_classification)
* [Token classification task guide](https://huggingface.co/docs/transformers/tasks/token_classification)
* [Question answering task guide](https://huggingface.co/docs/transformers/tasks/question_answering)
### MarkupLMConfig
#### class transformers.MarkupLMConfig
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/configuration_markuplm.py#L29)
( vocab\_size = 30522hidden\_size = 768num\_hidden\_layers = 12num\_attention\_heads = 12intermediate\_size = 3072hidden\_act = 'gelu'hidden\_dropout\_prob = 0.1attention\_probs\_dropout\_prob = 0.1max\_position\_embeddings = 512type\_vocab\_size = 2initializer\_range = 0.02layer\_norm\_eps = 1e-12pad\_token\_id = 0bos\_token\_id = 0eos\_token\_id = 2max\_xpath\_tag\_unit\_embeddings = 256max\_xpath\_subs\_unit\_embeddings = 1024tag\_pad\_id = 216subs\_pad\_id = 1001xpath\_unit\_hidden\_size = 32max\_depth = 50position\_embedding\_type = 'absolute'use\_cache = Trueclassifier\_dropout = None\*\*kwargs )
Parameters
* **vocab\_size** (`int`, *optional*, defaults to 30522) — Vocabulary size of the MarkupLM model. Defines the different tokens that can be represented by the *inputs\_ids* passed to the forward method of [MarkupLMModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMModel).
* **hidden\_size** (`int`, *optional*, defaults to 768) — Dimensionality of the encoder layers and the pooler layer.
* **num\_hidden\_layers** (`int`, *optional*, defaults to 12) — Number of hidden layers in the Transformer encoder.
* **num\_attention\_heads** (`int`, *optional*, defaults to 12) — Number of attention heads for each attention layer in the Transformer encoder.
* **intermediate\_size** (`int`, *optional*, defaults to 3072) — Dimensionality of the “intermediate” (i.e., feed-forward) layer in the Transformer encoder.
* **hidden\_act** (`str` or `function`, *optional*, defaults to `"gelu"`) — The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, `"relu"`, `"silu"` and `"gelu_new"` are supported.
* **hidden\_dropout\_prob** (`float`, *optional*, defaults to 0.1) — The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
* **attention\_probs\_dropout\_prob** (`float`, *optional*, defaults to 0.1) — The dropout ratio for the attention probabilities.
* **max\_position\_embeddings** (`int`, *optional*, defaults to 512) — The maximum sequence length that this model might ever be used with. Typically set this to something large just in case (e.g., 512 or 1024 or 2048).
* **type\_vocab\_size** (`int`, *optional*, defaults to 2) — The vocabulary size of the `token_type_ids` passed into [MarkupLMModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMModel).
* **initializer\_range** (`float`, *optional*, defaults to 0.02) — The standard deviation of the truncated\_normal\_initializer for initializing all weight matrices.
* **layer\_norm\_eps** (`float`, *optional*, defaults to 1e-12) — The epsilon used by the layer normalization layers.
* **max\_tree\_id\_unit\_embeddings** (`int`, *optional*, defaults to 1024) — The maximum value that the tree id unit embedding might ever use. Typically set this to something large just in case (e.g., 1024).
* **max\_xpath\_tag\_unit\_embeddings** (`int`, *optional*, defaults to 256) — The maximum value that the xpath tag unit embedding might ever use. Typically set this to something large just in case (e.g., 256).
* **max\_xpath\_subs\_unit\_embeddings** (`int`, *optional*, defaults to 1024) — The maximum value that the xpath subscript unit embedding might ever use. Typically set this to something large just in case (e.g., 1024).
* **tag\_pad\_id** (`int`, *optional*, defaults to 216) — The id of the padding token in the xpath tags.
* **subs\_pad\_id** (`int`, *optional*, defaults to 1001) — The id of the padding token in the xpath subscripts.
* **xpath\_tag\_unit\_hidden\_size** (`int`, *optional*, defaults to 32) — The hidden size of each tree id unit. One complete tree index will have (50\*xpath\_tag\_unit\_hidden\_size)-dim.
* **max\_depth** (`int`, *optional*, defaults to 50) — The maximum depth in xpath.
This is the configuration class to store the configuration of a [MarkupLMModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMModel). It is used to instantiate a MarkupLM model according to the specified arguments, defining the model architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of the MarkupLM [microsoft/markuplm-base](https://huggingface.co/microsoft/markuplm-base) architecture.
Configuration objects inherit from [BertConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/bert#transformers.BertConfig) and can be used to control the model outputs. Read the documentation from [BertConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/bert#transformers.BertConfig) for more information.
Examples:
Copied
```
>>> from transformers import MarkupLMModel, MarkupLMConfig
>>> # Initializing a MarkupLM microsoft/markuplm-base style configuration
>>> configuration = MarkupLMConfig()
>>> # Initializing a model from the microsoft/markuplm-base style configuration
>>> model = MarkupLMModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
### MarkupLMFeatureExtractor
#### class transformers.MarkupLMFeatureExtractor
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/feature_extraction_markuplm.py#L33)
( \*\*kwargs )
Constructs a MarkupLM feature extractor. This can be used to get a list of nodes and corresponding xpaths from HTML strings.
This feature extractor inherits from `PreTrainedFeatureExtractor()` which contains most of the main methods. Users should refer to this superclass for more information regarding those methods.
**\_\_call\_\_**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/feature_extraction_markuplm.py#L99)
( html\_strings ) → [BatchFeature](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/image_processor#transformers.BatchFeature)
Parameters
* **html\_strings** (`str`, `List[str]`) — The HTML string or batch of HTML strings from which to extract nodes and corresponding xpaths.
Returns
[BatchFeature](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/image_processor#transformers.BatchFeature)
A [BatchFeature](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/image_processor#transformers.BatchFeature) with the following fields:
* **nodes** — Nodes.
* **xpaths** — Corresponding xpaths.
Main method to prepare for the model one or several HTML strings.
Examples:
Copied
```
>>> from transformers import MarkupLMFeatureExtractor
>>> page_name_1 = "page1.html"
>>> page_name_2 = "page2.html"
>>> page_name_3 = "page3.html"
>>> with open(page_name_1) as f:
... single_html_string = f.read()
>>> feature_extractor = MarkupLMFeatureExtractor()
>>> # single example
>>> encoding = feature_extractor(single_html_string)
>>> print(encoding.keys())
>>> # dict_keys(['nodes', 'xpaths'])
>>> # batched example
>>> multi_html_strings = []
>>> with open(page_name_2) as f:
... multi_html_strings.append(f.read())
>>> with open(page_name_3) as f:
... multi_html_strings.append(f.read())
>>> encoding = feature_extractor(multi_html_strings)
>>> print(encoding.keys())
>>> # dict_keys(['nodes', 'xpaths'])
```
### MarkupLMTokenizer
#### class transformers.MarkupLMTokenizer
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm.py#L145)
( vocab\_filemerges\_filetags\_dicterrors = 'replace'bos\_token = '\'eos\_token = '\'sep\_token = '\'cls\_token = '\'unk\_token = '\'pad\_token = '\'mask\_token = '\'add\_prefix\_space = Falsemax\_depth = 50max\_width = 1000pad\_width = 1001pad\_token\_label = -100only\_label\_first\_subword = True\*\*kwargs )
Parameters
* **vocab\_file** (`str`) — Path to the vocabulary file.
* **merges\_file** (`str`) — Path to the merges file.
* **errors** (`str`, *optional*, defaults to `"replace"`) — Paradigm to follow when decoding bytes to UTF-8. See [bytes.decode](https://docs.python.org/3/library/stdtypes.html#bytes.decode) for more information.
* **bos\_token** (`str`, *optional*, defaults to `""`) — The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
When building a sequence using special tokens, this is not the token that is used for the beginning of sequence. The token used is the `cls_token`.
* **eos\_token** (`str`, *optional*, defaults to `""`) — The end of sequence token.
When building a sequence using special tokens, this is not the token that is used for the end of sequence. The token used is the `sep_token`.
* **sep\_token** (`str`, *optional*, defaults to `""`) — The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for sequence classification or for a text and a question for question answering. It is also used as the last token of a sequence built with special tokens.
* **cls\_token** (`str`, *optional*, defaults to `""`) — The classifier token which is used when doing sequence classification (classification of the whole sequence instead of per-token classification). It is the first token of the sequence when built with special tokens.
* **unk\_token** (`str`, *optional*, defaults to `""`) — The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this token instead.
* **pad\_token** (`str`, *optional*, defaults to `""`) — The token used for padding, for example when batching sequences of different lengths.
* **mask\_token** (`str`, *optional*, defaults to `""`) — The token used for masking values. This is the token used when training this model with masked language modeling. This is the token which the model will try to predict.
* **add\_prefix\_space** (`bool`, *optional*, defaults to `False`) — Whether or not to add an initial space to the input. This allows to treat the leading word just as any other word. (RoBERTa tokenizer detect beginning of words by the preceding space).
Construct a MarkupLM tokenizer. Based on byte-level Byte-Pair-Encoding (BPE). [MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) can be used to turn HTML strings into to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_tags_seq` and `xpath_tags_seq`. This tokenizer inherits from [PreTrainedTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizer) which contains most of the main methods. Users should refer to this superclass for more information regarding those methods.
**build\_inputs\_with\_special\_tokens**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm.py#L426)
( token\_ids\_0: typing.List\[int]token\_ids\_1: typing.Optional\[typing.List\[int]] = None ) → `List[int]`
Parameters
* **token\_ids\_0** (`List[int]`) — List of IDs to which the special tokens will be added.
* **token\_ids\_1** (`List[int]`, *optional*) — Optional second list of IDs for sequence pairs.
Returns
`List[int]`
List of [input IDs](https://huggingface.co/docs/transformers/glossary#input-ids) with the appropriate special tokens.
Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and adding special tokens. A RoBERTa sequence has the following format:
* single sequence: ` X `
* pair of sequences: ` A B `
**get\_special\_tokens\_mask**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm.py#L465)
( token\_ids\_0: typing.List\[int]token\_ids\_1: typing.Optional\[typing.List\[int]] = Nonealready\_has\_special\_tokens: bool = False ) → `List[int]`
Parameters
* **Retrieve** sequence ids from a token list that has no special tokens added. This method is called when adding —
* **special** tokens using the tokenizer `prepare_for_model` method. — token\_ids\_0 (`List[int]`): List of IDs. token\_ids\_1 (`List[int]`, *optional*): Optional second list of IDs for sequence pairs. already\_has\_special\_tokens (`bool`, *optional*, defaults to `False`): Whether or not the token list is already formatted with special tokens for the model.
Returns
`List[int]`
A list of integers in the range \[0, 1]: 1 for a special token, 0 for a sequence token.
**create\_token\_type\_ids\_from\_sequences**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm.py#L490)
( token\_ids\_0: typing.List\[int]token\_ids\_1: typing.Optional\[typing.List\[int]] = None ) → `List[int]`
Parameters
* **token\_ids\_0** (`List[int]`) — List of IDs.
* **token\_ids\_1** (`List[int]`, *optional*) — Optional second list of IDs for sequence pairs.
Returns
`List[int]`
List of zeros.
Create a mask from the two sequences passed to be used in a sequence-pair classification task. RoBERTa does not make use of token type ids, therefore a list of zeros is returned.
**save\_vocabulary**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm.py#L389)
( save\_directory: strfilename\_prefix: typing.Optional\[str] = None )
### MarkupLMTokenizerFast
#### class transformers.MarkupLMTokenizerFast
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L100)
( vocab\_filemerges\_filetags\_dicttokenizer\_file = Noneerrors = 'replace'bos\_token = '\'eos\_token = '\'sep\_token = '\'cls\_token = '\'unk\_token = '\'pad\_token = '\'mask\_token = '\'add\_prefix\_space = Falsemax\_depth = 50max\_width = 1000pad\_width = 1001pad\_token\_label = -100only\_label\_first\_subword = Truetrim\_offsets = False\*\*kwargs )
Parameters
* **vocab\_file** (`str`) — Path to the vocabulary file.
* **merges\_file** (`str`) — Path to the merges file.
* **errors** (`str`, *optional*, defaults to `"replace"`) — Paradigm to follow when decoding bytes to UTF-8. See [bytes.decode](https://docs.python.org/3/library/stdtypes.html#bytes.decode) for more information.
* **bos\_token** (`str`, *optional*, defaults to `""`) — The beginning of sequence token that was used during pretraining. Can be used a sequence classifier token.
When building a sequence using special tokens, this is not the token that is used for the beginning of sequence. The token used is the `cls_token`.
* **eos\_token** (`str`, *optional*, defaults to `""`) — The end of sequence token.
When building a sequence using special tokens, this is not the token that is used for the end of sequence. The token used is the `sep_token`.
* **sep\_token** (`str`, *optional*, defaults to `""`) — The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences for sequence classification or for a text and a question for question answering. It is also used as the last token of a sequence built with special tokens.
* **cls\_token** (`str`, *optional*, defaults to `""`) — The classifier token which is used when doing sequence classification (classification of the whole sequence instead of per-token classification). It is the first token of the sequence when built with special tokens.
* **unk\_token** (`str`, *optional*, defaults to `""`) — The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this token instead.
* **pad\_token** (`str`, *optional*, defaults to `""`) — The token used for padding, for example when batching sequences of different lengths.
* **mask\_token** (`str`, *optional*, defaults to `""`) — The token used for masking values. This is the token used when training this model with masked language modeling. This is the token which the model will try to predict.
* **add\_prefix\_space** (`bool`, *optional*, defaults to `False`) — Whether or not to add an initial space to the input. This allows to treat the leading word just as any other word. (RoBERTa tokenizer detect beginning of words by the preceding space).
Construct a MarkupLM tokenizer. Based on byte-level Byte-Pair-Encoding (BPE).
[MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast) can be used to turn HTML strings into to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_tags_seq` and `xpath_tags_seq`. This tokenizer inherits from [PreTrainedTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizer) which contains most of the main methods.
Users should refer to this superclass for more information regarding those methods.
**batch\_encode\_plus**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L440)
( batch\_text\_or\_text\_pairs: typing.Union\[typing.List\[str], typing.List\[typing.Tuple\[str, str]], typing.List\[typing.List\[str]]]is\_pair: bool = Nonexpaths: typing.Optional\[typing.List\[typing.List\[typing.List\[int]]]] = Nonenode\_labels: typing.Union\[typing.List\[int], typing.List\[typing.List\[int]], NoneType] = Noneadd\_special\_tokens: bool = Truepadding: typing.Union\[bool, str, transformers.utils.generic.PaddingStrategy] = Falsetruncation: typing.Union\[bool, str, transformers.tokenization\_utils\_base.TruncationStrategy] = Nonemax\_length: typing.Optional\[int] = Nonestride: int = 0pad\_to\_multiple\_of: typing.Optional\[int] = Nonereturn\_tensors: typing.Union\[str, transformers.utils.generic.TensorType, NoneType] = Nonereturn\_token\_type\_ids: typing.Optional\[bool] = Nonereturn\_attention\_mask: typing.Optional\[bool] = Nonereturn\_overflowing\_tokens: bool = Falsereturn\_special\_tokens\_mask: bool = Falsereturn\_offsets\_mapping: bool = Falsereturn\_length: bool = Falseverbose: bool = True\*\*kwargs )
add\_special\_tokens (`bool`, *optional*, defaults to `True`): Whether or not to add special tokens when encoding the sequences. This will use the underlying `PretrainedTokenizerBase.build_inputs_with_special_tokens` function, which defines which tokens are automatically added to the input ids. This is usefull if you want to add `bos` or `eos` tokens automatically. padding (`bool`, `str` or [PaddingStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.utils.PaddingStrategy), *optional*, defaults to `False`): Activates and controls padding. Accepts the following values:
* `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence if provided).
* `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided.
* `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different lengths). truncation (`bool`, `str` or [TruncationStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/tokenization_utils#transformers.tokenization_utils_base.TruncationStrategy), *optional*, defaults to `False`): Activates and controls truncation. Accepts the following values:
* `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will truncate token by token, removing a token from the longest sequence in the pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths greater than the model maximum admissible input size). max\_length (`int`, *optional*): Controls the maximum length to use by one of the truncation/padding parameters.
If left unset or set to `None`, this will use the predefined model maximum length if a maximum length is required by one of the truncation/padding parameters. If the model has no specific maximum input length (like XLNet) truncation/padding to a maximum length will be deactivated. stride (`int`, *optional*, defaults to 0): If set to a number along with `max_length`, the overflowing tokens returned when `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence returned to provide some overlap between truncated and overflowing sequences. The value of this argument defines the number of overlapping tokens. is\_split\_into\_words (`bool`, *optional*, defaults to `False`): Whether or not the input is already pre-tokenized (e.g., split into words). If set to `True`, the tokenizer assumes the input is already split into words (for instance, by splitting it on whitespace) which it will tokenize. This is useful for NER or token classification. pad\_to\_multiple\_of (`int`, *optional*): If set will pad the sequence to a multiple of the provided value. Requires `padding` to be activated. This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta). return\_tensors (`str` or [TensorType](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.TensorType), *optional*): If set, will return tensors instead of list of python integers. Acceptable values are:
* `'tf'`: Return TensorFlow `tf.constant` objects.
* `'pt'`: Return PyTorch `torch.Tensor` objects.
* `'np'`: Return Numpy `np.ndarray` objects.
add\_special\_tokens (`bool`, *optional*, defaults to `True`): Whether or not to encode the sequences with the special tokens relative to their model. padding (`bool`, `str` or [PaddingStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.utils.PaddingStrategy), *optional*, defaults to `False`): Activates and controls padding. Accepts the following values:
* `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence if provided).
* `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided.
* `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different lengths). truncation (`bool`, `str` or [TruncationStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/tokenization_utils#transformers.tokenization_utils_base.TruncationStrategy), *optional*, defaults to `False`): Activates and controls truncation. Accepts the following values:
* `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will truncate token by token, removing a token from the longest sequence in the pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths greater than the model maximum admissible input size). max\_length (`int`, *optional*): Controls the maximum length to use by one of the truncation/padding parameters. If left unset or set to `None`, this will use the predefined model maximum length if a maximum length is required by one of the truncation/padding parameters. If the model has no specific maximum input length (like XLNet) truncation/padding to a maximum length will be deactivated. stride (`int`, *optional*, defaults to 0): If set to a number along with `max_length`, the overflowing tokens returned when `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence returned to provide some overlap between truncated and overflowing sequences. The value of this argument defines the number of overlapping tokens. pad\_to\_multiple\_of (`int`, *optional*): If set will pad the sequence to a multiple of the provided value. This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta). return\_tensors (`str` or [TensorType](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.TensorType), *optional*): If set, will return tensors instead of list of python integers. Acceptable values are:
* `'tf'`: Return TensorFlow `tf.constant` objects.
* `'pt'`: Return PyTorch `torch.Tensor` objects.
* `'np'`: Return Numpy `np.ndarray` objects.
**build\_inputs\_with\_special\_tokens**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L890)
( token\_ids\_0: typing.List\[int]token\_ids\_1: typing.Optional\[typing.List\[int]] = None ) → `List[int]`
Parameters
* **token\_ids\_0** (`List[int]`) — List of IDs to which the special tokens will be added.
* **token\_ids\_1** (`List[int]`, *optional*) — Optional second list of IDs for sequence pairs.
Returns
`List[int]`
List of [input IDs](https://huggingface.co/docs/transformers/glossary#input-ids) with the appropriate special tokens.
Build model inputs from a sequence or a pair of sequence for sequence classification tasks by concatenating and adding special tokens. A RoBERTa sequence has the following format:
* single sequence: ` X `
* pair of sequences: ` A B `
**create\_token\_type\_ids\_from\_sequences**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L913)
( token\_ids\_0: typing.List\[int]token\_ids\_1: typing.Optional\[typing.List\[int]] = None ) → `List[int]`
Parameters
* **token\_ids\_0** (`List[int]`) — List of IDs.
* **token\_ids\_1** (`List[int]`, *optional*) — Optional second list of IDs for sequence pairs.
Returns
`List[int]`
List of zeros.
Create a mask from the two sequences passed to be used in a sequence-pair classification task. RoBERTa does not make use of token type ids, therefore a list of zeros is returned.
**encode\_plus**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L507)
( text: typing.Union\[str, typing.List\[str]]text\_pair: typing.Optional\[typing.List\[str]] = Nonexpaths: typing.Optional\[typing.List\[typing.List\[int]]] = Nonenode\_labels: typing.Optional\[typing.List\[int]] = Noneadd\_special\_tokens: bool = Truepadding: typing.Union\[bool, str, transformers.utils.generic.PaddingStrategy] = Falsetruncation: typing.Union\[bool, str, transformers.tokenization\_utils\_base.TruncationStrategy] = Nonemax\_length: typing.Optional\[int] = Nonestride: int = 0pad\_to\_multiple\_of: typing.Optional\[int] = Nonereturn\_tensors: typing.Union\[str, transformers.utils.generic.TensorType, NoneType] = Nonereturn\_token\_type\_ids: typing.Optional\[bool] = Nonereturn\_attention\_mask: typing.Optional\[bool] = Nonereturn\_overflowing\_tokens: bool = Falsereturn\_special\_tokens\_mask: bool = Falsereturn\_offsets\_mapping: bool = Falsereturn\_length: bool = Falseverbose: bool = True\*\*kwargs )
Parameters
* **text** (`str`, `List[str]`, `List[List[str]]`) — The first sequence to be encoded. This can be a string, a list of strings or a list of list of strings.
* **text\_pair** (`List[str]` or `List[int]`, *optional*) — Optional second sequence to be encoded. This can be a list of strings (words of a single example) or a list of list of strings (words of a batch of examples).
* **add\_special\_tokens** (`bool`, *optional*, defaults to `True`) — Whether or not to add special tokens when encoding the sequences. This will use the underlying `PretrainedTokenizerBase.build_inputs_with_special_tokens` function, which defines which tokens are automatically added to the input ids. This is usefull if you want to add `bos` or `eos` tokens automatically.
* **padding** (`bool`, `str` or [PaddingStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.utils.PaddingStrategy), *optional*, defaults to `False`) — Activates and controls padding. Accepts the following values:
* `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence if provided).
* `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided.
* `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different lengths).
* **truncation** (`bool`, `str` or [TruncationStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/tokenization_utils#transformers.tokenization_utils_base.TruncationStrategy), *optional*, defaults to `False`) — Activates and controls truncation. Accepts the following values:
* `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will truncate token by token, removing a token from the longest sequence in the pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths greater than the model maximum admissible input size).
* **max\_length** (`int`, *optional*) — Controls the maximum length to use by one of the truncation/padding parameters.
If left unset or set to `None`, this will use the predefined model maximum length if a maximum length is required by one of the truncation/padding parameters. If the model has no specific maximum input length (like XLNet) truncation/padding to a maximum length will be deactivated.
* **stride** (`int`, *optional*, defaults to 0) — If set to a number along with `max_length`, the overflowing tokens returned when `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence returned to provide some overlap between truncated and overflowing sequences. The value of this argument defines the number of overlapping tokens.
* **is\_split\_into\_words** (`bool`, *optional*, defaults to `False`) — Whether or not the input is already pre-tokenized (e.g., split into words). If set to `True`, the tokenizer assumes the input is already split into words (for instance, by splitting it on whitespace) which it will tokenize. This is useful for NER or token classification.
* **pad\_to\_multiple\_of** (`int`, *optional*) — If set will pad the sequence to a multiple of the provided value. Requires `padding` to be activated. This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
* **return\_tensors** (`str` or [TensorType](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.TensorType), *optional*) — If set, will return tensors instead of list of python integers. Acceptable values are:
* `'tf'`: Return TensorFlow `tf.constant` objects.
* `'pt'`: Return PyTorch `torch.Tensor` objects.
* `'np'`: Return Numpy `np.ndarray` objects.
* **add\_special\_tokens** (`bool`, *optional*, defaults to `True`) — Whether or not to encode the sequences with the special tokens relative to their model.
* **padding** (`bool`, `str` or [PaddingStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.utils.PaddingStrategy), *optional*, defaults to `False`) — Activates and controls padding. Accepts the following values:
* `True` or `'longest'`: Pad to the longest sequence in the batch (or no padding if only a single sequence if provided).
* `'max_length'`: Pad to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided.
* `False` or `'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of different lengths).
* **truncation** (`bool`, `str` or [TruncationStrategy](https://huggingface.co/docs/transformers/v4.34.1/en/internal/tokenization_utils#transformers.tokenization_utils_base.TruncationStrategy), *optional*, defaults to `False`) — Activates and controls truncation. Accepts the following values:
* `True` or `'longest_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will truncate token by token, removing a token from the longest sequence in the pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_first'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the first sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `'only_second'`: Truncate to a maximum length specified with the argument `max_length` or to the maximum acceptable input length for the model if that argument is not provided. This will only truncate the second sequence of a pair if a pair of sequences (or a batch of pairs) is provided.
* `False` or `'do_not_truncate'` (default): No truncation (i.e., can output batch with sequence lengths greater than the model maximum admissible input size).
* **max\_length** (`int`, *optional*) — Controls the maximum length to use by one of the truncation/padding parameters. If left unset or set to `None`, this will use the predefined model maximum length if a maximum length is required by one of the truncation/padding parameters. If the model has no specific maximum input length (like XLNet) truncation/padding to a maximum length will be deactivated.
* **stride** (`int`, *optional*, defaults to 0) — If set to a number along with `max_length`, the overflowing tokens returned when `return_overflowing_tokens=True` will contain some tokens from the end of the truncated sequence returned to provide some overlap between truncated and overflowing sequences. The value of this argument defines the number of overlapping tokens.
* **pad\_to\_multiple\_of** (`int`, *optional*) — If set will pad the sequence to a multiple of the provided value. This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability `>= 7.5` (Volta).
* **return\_tensors** (`str` or [TensorType](https://huggingface.co/docs/transformers/v4.34.1/en/internal/file_utils#transformers.TensorType), *optional*) — If set, will return tensors instead of list of python integers. Acceptable values are:
* `'tf'`: Return TensorFlow `tf.constant` objects.
* `'pt'`: Return PyTorch `torch.Tensor` objects.
* `'np'`: Return Numpy `np.ndarray` objects.
Tokenize and prepare for the model a sequence or a pair of sequences. .. warning:: This method is deprecated, `__call__` should be used instead.
**get\_xpath\_seq**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/tokenization_markuplm_fast.py#L270)
( xpath )
Given the xpath expression of one particular node (like “/html/body/div/li\[1]/div/span\[2]”), return a list of tag IDs and corresponding subscripts, taking into account max depth.
### MarkupLMProcessor
#### class transformers.MarkupLMProcessor
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/processing_markuplm.py#L25)
( \*args\*\*kwargs )
Parameters
* **feature\_extractor** (`MarkupLMFeatureExtractor`) — An instance of [MarkupLMFeatureExtractor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor). The feature extractor is a required input.
* **tokenizer** (`MarkupLMTokenizer` or `MarkupLMTokenizerFast`) — An instance of [MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) or [MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast). The tokenizer is a required input.
* **parse\_html** (`bool`, *optional*, defaults to `True`) — Whether or not to use `MarkupLMFeatureExtractor` to parse HTML strings into nodes and corresponding xpaths.
Constructs a MarkupLM processor which combines a MarkupLM feature extractor and a MarkupLM tokenizer into a single processor.
[MarkupLMProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMProcessor) offers all the functionalities you need to prepare data for the model.
It first uses [MarkupLMFeatureExtractor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor) to extract nodes and corresponding xpaths from one or more HTML strings. Next, these are provided to [MarkupLMTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizer) or [MarkupLMTokenizerFast](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMTokenizerFast), which turns them into token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_tags_seq` and `xpath_subs_seq`.
**\_\_call\_\_**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/processing_markuplm.py#L48)
( html\_strings = Nonenodes = Nonexpaths = Nonenode\_labels = Nonequestions = Noneadd\_special\_tokens: bool = Truepadding: typing.Union\[bool, str, transformers.utils.generic.PaddingStrategy] = Falsetruncation: typing.Union\[bool, str, transformers.tokenization\_utils\_base.TruncationStrategy] = Nonemax\_length: typing.Optional\[int] = Nonestride: int = 0pad\_to\_multiple\_of: typing.Optional\[int] = Nonereturn\_token\_type\_ids: typing.Optional\[bool] = Nonereturn\_attention\_mask: typing.Optional\[bool] = Nonereturn\_overflowing\_tokens: bool = Falsereturn\_special\_tokens\_mask: bool = Falsereturn\_offsets\_mapping: bool = Falsereturn\_length: bool = Falseverbose: bool = Truereturn\_tensors: typing.Union\[str, transformers.utils.generic.TensorType, NoneType] = None\*\*kwargs )
This method first forwards the `html_strings` argument to [**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMFeatureExtractor.__call__). Next, it passes the `nodes` and `xpaths` along with the additional arguments to `__call__()` and returns the output.
Optionally, one can also provide a `text` argument which is passed along as first sequence.
Please refer to the docstring of the above two methods for more information.
### MarkupLMModel
#### class transformers.MarkupLMModel
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L807)
( configadd\_pooling\_layer = True )
Parameters
* **config** ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
The bare MarkupLM Model transformer outputting raw hidden-states without any specific head on top. This model is a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) sub-class. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L835)
( input\_ids: typing.Optional\[torch.LongTensor] = Nonexpath\_tags\_seq: typing.Optional\[torch.LongTensor] = Nonexpath\_subs\_seq: typing.Optional\[torch.LongTensor] = Noneattention\_mask: typing.Optional\[torch.FloatTensor] = Nonetoken\_type\_ids: typing.Optional\[torch.LongTensor] = Noneposition\_ids: typing.Optional\[torch.LongTensor] = Nonehead\_mask: typing.Optional\[torch.FloatTensor] = Noneinputs\_embeds: typing.Optional\[torch.FloatTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.BaseModelOutputWithPoolingAndCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions) or `tuple(torch.FloatTensor)`
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **xpath\_tags\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Tag IDs for each token in the input sequence, padded up to config.max\_depth.
* **xpath\_subs\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Subscript IDs for each token in the input sequence, padded up to config.max\_depth.
* **attention\_mask** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **token\_type\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, 1]`: `0` corresponds to a *sentence A* token, `1` corresponds to a *sentence B* token
[What are token type IDs?](https://huggingface.co/docs/transformers/glossary#token-type-ids)
* **position\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, config.max_position_embeddings - 1]`.
[What are position IDs?](https://huggingface.co/docs/transformers/glossary#position-ids)
* **head\_mask** (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*) — Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`: `1` indicates the head is **not masked**, `0` indicates the head is **masked**.
* **inputs\_embeds** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) — Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more control over how to convert *input\_ids* indices into associated vectors than the model’s internal embedding lookup matrix.
* **output\_attentions** (`bool`, *optional*) — If set to `True`, the attentions tensors of all attention layers are returned. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — If set to `True`, the hidden states of all layers are returned. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — If set to `True`, the model will return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
[transformers.modeling\_outputs.BaseModelOutputWithPoolingAndCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.BaseModelOutputWithPoolingAndCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) and inputs.
* **last\_hidden\_state** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`) — Sequence of hidden-states at the output of the last layer of the model.
* **pooler\_output** (`torch.FloatTensor` of shape `(batch_size, hidden_size)`) — Last layer hidden-state of the first token of the sequence (classification token) after further processing through the layers used for the auxiliary pretraining task. E.g. for BERT-family of models, this returns the classification token after processing through a linear layer and a tanh activation function. The linear layer weights are trained from the next sentence prediction (classification) objective during pretraining.
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
* **cross\_attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` and `config.add_cross_attention=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights of the decoder’s cross-attention layer, after the attention softmax, used to compute the weighted average in the cross-attention heads.
* **past\_key\_values** (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`) — Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and optionally if `config.is_encoder_decoder=True` 2 additional tensors of shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`.
Contains pre-computed hidden-states (key and values in the self-attention blocks and optionally if `config.is_encoder_decoder=True` in the cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
The [MarkupLMModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMModel) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> from transformers import AutoProcessor, MarkupLMModel
>>> processor = AutoProcessor.from_pretrained("microsoft/markuplm-base")
>>> model = MarkupLMModel.from_pretrained("microsoft/markuplm-base")
>>> html_string = " Page Title "
>>> encoding = processor(html_string, return_tensors="pt")
>>> outputs = model(**encoding)
>>> last_hidden_states = outputs.last_hidden_state
>>> list(last_hidden_states.shape)
[1, 4, 768]
```
### MarkupLMForSequenceClassification
#### class transformers.MarkupLMForSequenceClassification
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L1203)
( config )
Parameters
* **config** ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
MarkupLM Model transformer with a sequence classification/regression head on top (a linear layer on top of the pooled output) e.g. for GLUE tasks.
This model is a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) sub-class. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L1220)
( input\_ids: typing.Optional\[torch.Tensor] = Nonexpath\_tags\_seq: typing.Optional\[torch.Tensor] = Nonexpath\_subs\_seq: typing.Optional\[torch.Tensor] = Noneattention\_mask: typing.Optional\[torch.Tensor] = Nonetoken\_type\_ids: typing.Optional\[torch.Tensor] = Noneposition\_ids: typing.Optional\[torch.Tensor] = Nonehead\_mask: typing.Optional\[torch.Tensor] = Noneinputs\_embeds: typing.Optional\[torch.Tensor] = Nonelabels: typing.Optional\[torch.Tensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.SequenceClassifierOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.SequenceClassifierOutput) or `tuple(torch.FloatTensor)`
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **xpath\_tags\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Tag IDs for each token in the input sequence, padded up to config.max\_depth.
* **xpath\_subs\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Subscript IDs for each token in the input sequence, padded up to config.max\_depth.
* **attention\_mask** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **token\_type\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, 1]`: `0` corresponds to a *sentence A* token, `1` corresponds to a *sentence B* token
[What are token type IDs?](https://huggingface.co/docs/transformers/glossary#token-type-ids)
* **position\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, config.max_position_embeddings - 1]`.
[What are position IDs?](https://huggingface.co/docs/transformers/glossary#position-ids)
* **head\_mask** (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*) — Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`: `1` indicates the head is **not masked**, `0` indicates the head is **masked**.
* **inputs\_embeds** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) — Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more control over how to convert *input\_ids* indices into associated vectors than the model’s internal embedding lookup matrix.
* **output\_attentions** (`bool`, *optional*) — If set to `True`, the attentions tensors of all attention layers are returned. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — If set to `True`, the hidden states of all layers are returned. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — If set to `True`, the model will return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
* **labels** (`torch.LongTensor` of shape `(batch_size,)`, *optional*) — Labels for computing the sequence classification/regression loss. Indices should be in `[0, ..., config.num_labels - 1]`. If `config.num_labels == 1` a regression loss is computed (Mean-Square loss), If `config.num_labels > 1` a classification loss is computed (Cross-Entropy).
Returns
[transformers.modeling\_outputs.SequenceClassifierOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.SequenceClassifierOutput) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.SequenceClassifierOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.SequenceClassifierOutput) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) and inputs.
* **loss** (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided) — Classification (or regression if config.num\_labels==1) loss.
* **logits** (`torch.FloatTensor` of shape `(batch_size, config.num_labels)`) — Classification (or regression if config.num\_labels==1) scores (before SoftMax).
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
The [MarkupLMForSequenceClassification](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMForSequenceClassification) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> from transformers import AutoProcessor, AutoModelForSequenceClassification
>>> import torch
>>> processor = AutoProcessor.from_pretrained("microsoft/markuplm-base")
>>> model = AutoModelForSequenceClassification.from_pretrained("microsoft/markuplm-base", num_labels=7)
>>> html_string = " Page Title "
>>> encoding = processor(html_string, return_tensors="pt")
>>> with torch.no_grad():
... outputs = model(**encoding)
>>> loss = outputs.loss
>>> logits = outputs.logits
```
### MarkupLMForTokenClassification
#### class transformers.MarkupLMForTokenClassification
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L1097)
( config )
Parameters
* **config** ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
MarkupLM Model with a `token_classification` head on top. This model is a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) sub-class. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L1113)
( input\_ids: typing.Optional\[torch.Tensor] = Nonexpath\_tags\_seq: typing.Optional\[torch.Tensor] = Nonexpath\_subs\_seq: typing.Optional\[torch.Tensor] = Noneattention\_mask: typing.Optional\[torch.Tensor] = Nonetoken\_type\_ids: typing.Optional\[torch.Tensor] = Noneposition\_ids: typing.Optional\[torch.Tensor] = Nonehead\_mask: typing.Optional\[torch.Tensor] = Noneinputs\_embeds: typing.Optional\[torch.Tensor] = Nonelabels: typing.Optional\[torch.Tensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.MaskedLMOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.MaskedLMOutput) or `tuple(torch.FloatTensor)`
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **xpath\_tags\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Tag IDs for each token in the input sequence, padded up to config.max\_depth.
* **xpath\_subs\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Subscript IDs for each token in the input sequence, padded up to config.max\_depth.
* **attention\_mask** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **token\_type\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, 1]`: `0` corresponds to a *sentence A* token, `1` corresponds to a *sentence B* token
[What are token type IDs?](https://huggingface.co/docs/transformers/glossary#token-type-ids)
* **position\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, config.max_position_embeddings - 1]`.
[What are position IDs?](https://huggingface.co/docs/transformers/glossary#position-ids)
* **head\_mask** (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*) — Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`: `1` indicates the head is **not masked**, `0` indicates the head is **masked**.
* **inputs\_embeds** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) — Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more control over how to convert *input\_ids* indices into associated vectors than the model’s internal embedding lookup matrix.
* **output\_attentions** (`bool`, *optional*) — If set to `True`, the attentions tensors of all attention layers are returned. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — If set to `True`, the hidden states of all layers are returned. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — If set to `True`, the model will return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
* **labels** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Labels for computing the token classification loss. Indices should be in `[0, ..., config.num_labels - 1]`.
Returns
[transformers.modeling\_outputs.MaskedLMOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.MaskedLMOutput) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.MaskedLMOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.MaskedLMOutput) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) and inputs.
* **loss** (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided) — Masked language modeling (MLM) loss.
* **logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) — Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
The [MarkupLMForTokenClassification](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMForTokenClassification) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> from transformers import AutoProcessor, AutoModelForTokenClassification
>>> import torch
>>> processor = AutoProcessor.from_pretrained("microsoft/markuplm-base")
>>> processor.parse_html = False
>>> model = AutoModelForTokenClassification.from_pretrained("microsoft/markuplm-base", num_labels=7)
>>> nodes = ["hello", "world"]
>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span"]
>>> node_labels = [1, 2]
>>> encoding = processor(nodes=nodes, xpaths=xpaths, node_labels=node_labels, return_tensors="pt")
>>> with torch.no_grad():
... outputs = model(**encoding)
>>> loss = outputs.loss
>>> logits = outputs.logits
```
### MarkupLMForQuestionAnswering
#### class transformers.MarkupLMForQuestionAnswering
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L977)
( config )
Parameters
* **config** ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
MarkupLM Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear layers on top of the hidden-states output to compute `span start logits` and `span end logits`).
This model is a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) sub-class. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/markuplm/modeling_markuplm.py#L989)
( input\_ids: typing.Optional\[torch.Tensor] = Nonexpath\_tags\_seq: typing.Optional\[torch.Tensor] = Nonexpath\_subs\_seq: typing.Optional\[torch.Tensor] = Noneattention\_mask: typing.Optional\[torch.Tensor] = Nonetoken\_type\_ids: typing.Optional\[torch.Tensor] = Noneposition\_ids: typing.Optional\[torch.Tensor] = Nonehead\_mask: typing.Optional\[torch.Tensor] = Noneinputs\_embeds: typing.Optional\[torch.Tensor] = Nonestart\_positions: typing.Optional\[torch.Tensor] = Noneend\_positions: typing.Optional\[torch.Tensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.QuestionAnsweringModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.QuestionAnsweringModelOutput) or `tuple(torch.FloatTensor)`
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **xpath\_tags\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Tag IDs for each token in the input sequence, padded up to config.max\_depth.
* **xpath\_subs\_seq** (`torch.LongTensor` of shape `(batch_size, sequence_length, config.max_depth)`, *optional*) — Subscript IDs for each token in the input sequence, padded up to config.max\_depth.
* **attention\_mask** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`: `1` for tokens that are NOT MASKED, `0` for MASKED tokens.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **token\_type\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Segment token indices to indicate first and second portions of the inputs. Indices are selected in `[0, 1]`: `0` corresponds to a *sentence A* token, `1` corresponds to a *sentence B* token
[What are token type IDs?](https://huggingface.co/docs/transformers/glossary#token-type-ids)
* **position\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of positions of each input sequence tokens in the position embeddings. Selected in the range `[0, config.max_position_embeddings - 1]`.
[What are position IDs?](https://huggingface.co/docs/transformers/glossary#position-ids)
* **head\_mask** (`torch.FloatTensor` of shape `(num_heads,)` or `(num_layers, num_heads)`, *optional*) — Mask to nullify selected heads of the self-attention modules. Mask values selected in `[0, 1]`: `1` indicates the head is **not masked**, `0` indicates the head is **masked**.
* **inputs\_embeds** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) — Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation. This is useful if you want more control over how to convert *input\_ids* indices into associated vectors than the model’s internal embedding lookup matrix.
* **output\_attentions** (`bool`, *optional*) — If set to `True`, the attentions tensors of all attention layers are returned. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — If set to `True`, the hidden states of all layers are returned. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — If set to `True`, the model will return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
* **start\_positions** (`torch.LongTensor` of shape `(batch_size,)`, *optional*) — Labels for position (index) of the start of the labelled span for computing the token classification loss. Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence are not taken into account for computing the loss.
* **end\_positions** (`torch.LongTensor` of shape `(batch_size,)`, *optional*) — Labels for position (index) of the end of the labelled span for computing the token classification loss. Positions are clamped to the length of the sequence (`sequence_length`). Position outside of the sequence are not taken into account for computing the loss.
Returns
[transformers.modeling\_outputs.QuestionAnsweringModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.QuestionAnsweringModelOutput) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.QuestionAnsweringModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.QuestionAnsweringModelOutput) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration ([MarkupLMConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMConfig)) and inputs.
* **loss** (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided) — Total span extraction loss is the sum of a Cross-Entropy for the start and end positions.
* **start\_logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`) — Span-start scores (before SoftMax).
* **end\_logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`) — Span-end scores (before SoftMax).
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
The [MarkupLMForQuestionAnswering](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/markuplm#transformers.MarkupLMForQuestionAnswering) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> from transformers import AutoProcessor, MarkupLMForQuestionAnswering
>>> import torch
>>> processor = AutoProcessor.from_pretrained("microsoft/markuplm-base-finetuned-websrc")
>>> model = MarkupLMForQuestionAnswering.from_pretrained("microsoft/markuplm-base-finetuned-websrc")
>>> html_string = " My name is Niels "
>>> question = "What's his name?"
>>> encoding = processor(html_string, questions=question, return_tensors="pt")
>>> with torch.no_grad():
... outputs = model(**encoding)
>>> answer_start_index = outputs.start_logits.argmax()
>>> answer_end_index = outputs.end_logits.argmax()
>>> predict_answer_tokens = encoding.input_ids[0, answer_start_index : answer_end_index + 1]
>>> processor.decode(predict_answer_tokens).strip()
'Niels'
```