> For the complete documentation index, see [llms.txt](https://boinc-ai.gitbook.io/transformers/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://boinc-ai.gitbook.io/transformers/api/models/multimodal-models/blip-2.md).
# BLIP-2
## BLIP-2
### Overview
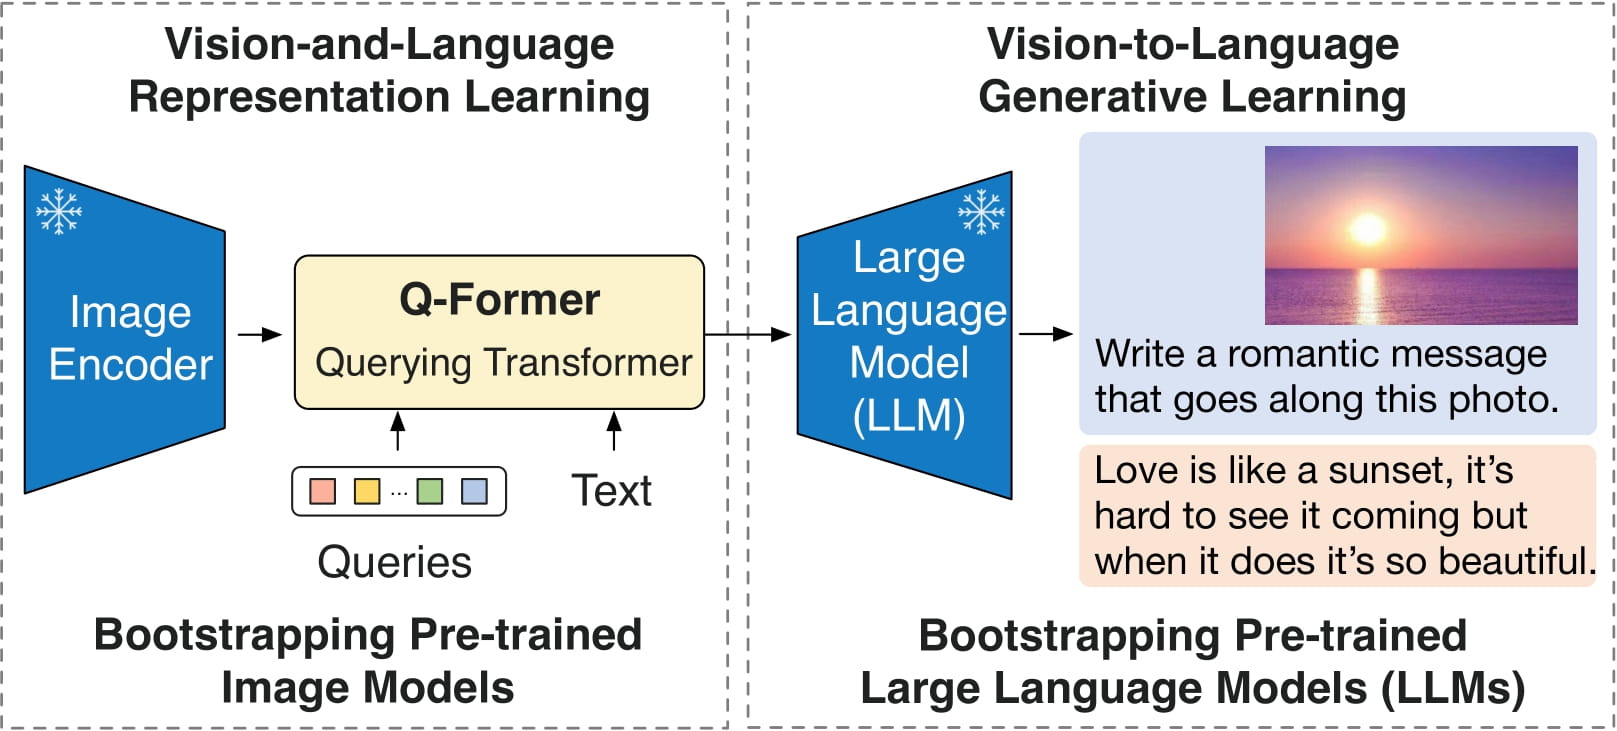
The BLIP-2 model was proposed in [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) by Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi. BLIP-2 leverages frozen pre-trained image encoders and large language models (LLMs) by training a lightweight, 12-layer Transformer encoder in between them, achieving state-of-the-art performance on various vision-language tasks. Most notably, BLIP-2 improves upon [Flamingo](https://arxiv.org/abs/2204.14198), an 80 billion parameter model, by 8.7% on zero-shot VQAv2 with 54x fewer trainable parameters.
The abstract from the paper is the following:
*The cost of vision-and-language pre-training has become increasingly prohibitive due to end-to-end training of large-scale models. This paper proposes BLIP-2, a generic and efficient pre-training strategy that bootstraps vision-language pre-training from off-the-shelf frozen pre-trained image encoders and frozen large language models. BLIP-2 bridges the modality gap with a lightweight Querying Transformer, which is pre-trained in two stages. The first stage bootstraps vision-language representation learning from a frozen image encoder. The second stage bootstraps vision-to-language generative learning from a frozen language model. BLIP-2 achieves state-of-the-art performance on various vision-language tasks, despite having significantly fewer trainable parameters than existing methods. For example, our model outperforms Flamingo80B by 8.7% on zero-shot VQAv2 with 54x fewer trainable parameters. We also demonstrate the model’s emerging capabilities of zero-shot image-to-text generation that can follow natural language instructions.*
Tips:
* BLIP-2 can be used for conditional text generation given an image and an optional text prompt. At inference time, it’s recommended to use the `generate` method.
* One can use [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor) to prepare images for the model, and decode the predicted tokens ID’s back to text.
BLIP-2 architecture. Taken from the [original paper.](https://arxiv.org/abs/2301.12597)
This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/salesforce/LAVIS/tree/5ee63d688ba4cebff63acee04adaef2dee9af207).
### Resources
A list of official BOINC AI and community (indicated by 🌎) resources to help you get started with BLIP-2.
* Demo notebooks for BLIP-2 for image captioning, visual question answering (VQA) and chat-like conversations can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BLIP-2).
If you’re interested in submitting a resource to be included here, please feel free to open a Pull Request and we’ll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
### Blip2Config
#### class transformers.Blip2Config
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/configuration_blip_2.py#L250)
( vision\_config = Noneqformer\_config = Nonetext\_config = Nonenum\_query\_tokens = 32\*\*kwargs )
Parameters
* **vision\_config** (`dict`, *optional*) — Dictionary of configuration options used to initialize [Blip2VisionConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2VisionConfig).
* **qformer\_config** (`dict`, *optional*) — Dictionary of configuration options used to initialize [Blip2QFormerConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2QFormerConfig).
* **text\_config** (`dict`, *optional*) — Dictionary of configuration options used to initialize any [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig).
* **num\_query\_tokens** (`int`, *optional*, defaults to 32) — The number of query tokens passed through the Transformer.
* **kwargs** (*optional*) — Dictionary of keyword arguments.
[Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config) is the configuration class to store the configuration of a [Blip2ForConditionalGeneration](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2ForConditionalGeneration). It is used to instantiate a BLIP-2 model according to the specified arguments, defining the vision model, Q-Former model and language model configs. Instantiating a configuration with the defaults will yield a similar configuration to that of the BLIP-2 [Salesforce/blip2-opt-2.7b](https://huggingface.co/Salesforce/blip2-opt-2.7b) architecture.
Configuration objects inherit from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) and can be used to control the model outputs. Read the documentation from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) for more information.
Example:
Copied
```
>>> from transformers import (
... Blip2VisionConfig,
... Blip2QFormerConfig,
... OPTConfig,
... Blip2Config,
... Blip2ForConditionalGeneration,
... )
>>> # Initializing a Blip2Config with Salesforce/blip2-opt-2.7b style configuration
>>> configuration = Blip2Config()
>>> # Initializing a Blip2ForConditionalGeneration (with random weights) from the Salesforce/blip2-opt-2.7b style configuration
>>> model = Blip2ForConditionalGeneration(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
>>> # We can also initialize a Blip2Config from a Blip2VisionConfig, Blip2QFormerConfig and any PretrainedConfig
>>> # Initializing BLIP-2 vision, BLIP-2 Q-Former and language model configurations
>>> vision_config = Blip2VisionConfig()
>>> qformer_config = Blip2QFormerConfig()
>>> text_config = OPTConfig()
>>> config = Blip2Config.from_text_vision_configs(vision_config, qformer_config, text_config)
```
**from\_vision\_qformer\_text\_configs**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/configuration_blip_2.py#L334)
( vision\_config: Blip2VisionConfigqformer\_config: Blip2QFormerConfigtext\_config: PretrainedConfig\*\*kwargs ) → [Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config)
Returns
[Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config)
An instance of a configuration object
Instantiate a [Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config) (or a derived class) from a BLIP-2 vision model, Q-Former and language model configurations.
### Blip2VisionConfig
#### class transformers.Blip2VisionConfig
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/configuration_blip_2.py#L33)
( hidden\_size = 1408intermediate\_size = 6144num\_hidden\_layers = 39num\_attention\_heads = 16image\_size = 224patch\_size = 14hidden\_act = 'gelu'layer\_norm\_eps = 1e-06attention\_dropout = 0.0initializer\_range = 1e-10qkv\_bias = True\*\*kwargs )
Parameters
* **hidden\_size** (`int`, *optional*, defaults to 1408) — Dimensionality of the encoder layers and the pooler layer.
* **intermediate\_size** (`int`, *optional*, defaults to 6144) — Dimensionality of the “intermediate” (i.e., feed-forward) layer in the Transformer encoder.
* **num\_hidden\_layers** (`int`, *optional*, defaults to 39) — Number of hidden layers in the Transformer encoder.
* **num\_attention\_heads** (`int`, *optional*, defaults to 16) — Number of attention heads for each attention layer in the Transformer encoder.
* **image\_size** (`int`, *optional*, defaults to 224) — The size (resolution) of each image.
* **patch\_size** (`int`, *optional*, defaults to 14) — The size (resolution) of each patch.
* **hidden\_act** (`str` or `function`, *optional*, defaults to `"gelu"`) — The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, `"relu"`, `"selu"` and `"gelu_new"` \``"gelu"` are supported. layer\_norm\_eps (`float`, *optional*, defaults to 1e-5): The epsilon used by the layer normalization layers.
* **attention\_dropout** (`float`, *optional*, defaults to 0.0) — The dropout ratio for the attention probabilities.
* **initializer\_range** (`float`, *optional*, defaults to 0.02) — The standard deviation of the truncated\_normal\_initializer for initializing all weight matrices.
* **qkv\_bias** (`bool`, *optional*, defaults to `True`) — Whether to add a bias to the queries and values in the self-attention layers.
This is the configuration class to store the configuration of a [Blip2VisionModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2VisionModel). It is used to instantiate a BLIP-2 vision encoder according to the specified arguments, defining the model architecture. Instantiating a configuration defaults will yield a similar configuration to that of the BLIP-2 [Salesforce/blip2-opt-2.7b](https://huggingface.co/Salesforce/blip2-opt-2.7b) architecture.
Configuration objects inherit from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) and can be used to control the model outputs. Read the documentation from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) for more information.
Example:
Copied
```
>>> from transformers import Blip2VisionConfig, Blip2VisionModel
>>> # Initializing a Blip2VisionConfig with Salesforce/blip2-opt-2.7b style configuration
>>> configuration = Blip2VisionConfig()
>>> # Initializing a Blip2VisionModel (with random weights) from the Salesforce/blip2-opt-2.7b style configuration
>>> model = Blip2VisionModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
### Blip2QFormerConfig
#### class transformers.Blip2QFormerConfig
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/configuration_blip_2.py#L132)
( vocab\_size = 30522hidden\_size = 768num\_hidden\_layers = 12num\_attention\_heads = 12intermediate\_size = 3072hidden\_act = 'gelu'hidden\_dropout\_prob = 0.1attention\_probs\_dropout\_prob = 0.1max\_position\_embeddings = 512initializer\_range = 0.02layer\_norm\_eps = 1e-12pad\_token\_id = 0position\_embedding\_type = 'absolute'cross\_attention\_frequency = 2encoder\_hidden\_size = 1408\*\*kwargs )
Parameters
* **vocab\_size** (`int`, *optional*, defaults to 30522) — Vocabulary size of the Q-Former model. Defines the number of different tokens that can be represented by the `inputs_ids` passed when calling the model.
* **hidden\_size** (`int`, *optional*, defaults to 768) — Dimensionality of the encoder layers and the pooler layer.
* **num\_hidden\_layers** (`int`, *optional*, defaults to 12) — Number of hidden layers in the Transformer encoder.
* **num\_attention\_heads** (`int`, *optional*, defaults to 12) — Number of attention heads for each attention layer in the Transformer encoder.
* **intermediate\_size** (`int`, *optional*, defaults to 3072) — Dimensionality of the “intermediate” (often named feed-forward) layer in the Transformer encoder.
* **hidden\_act** (`str` or `Callable`, *optional*, defaults to `"gelu"`) — The non-linear activation function (function or string) in the encoder and pooler. If string, `"gelu"`, `"relu"`, `"silu"` and `"gelu_new"` are supported.
* **hidden\_dropout\_prob** (`float`, *optional*, defaults to 0.1) — The dropout probability for all fully connected layers in the embeddings, encoder, and pooler.
* **attention\_probs\_dropout\_prob** (`float`, *optional*, defaults to 0.1) — The dropout ratio for the attention probabilities.
* **max\_position\_embeddings** (`int`, *optional*, defaults to 512) — The maximum sequence length that this model might ever be used with. Typically set this to something large just in case (e.g., 512 or 1024 or 2048).
* **initializer\_range** (`float`, *optional*, defaults to 0.02) — The standard deviation of the truncated\_normal\_initializer for initializing all weight matrices.
* **layer\_norm\_eps** (`float`, *optional*, defaults to 1e-12) — The epsilon used by the layer normalization layers.
* **position\_embedding\_type** (`str`, *optional*, defaults to `"absolute"`) — Type of position embedding. Choose one of `"absolute"`, `"relative_key"`, `"relative_key_query"`. For positional embeddings use `"absolute"`. For more information on `"relative_key"`, please refer to [Self-Attention with Relative Position Representations (Shaw et al.)](https://arxiv.org/abs/1803.02155). For more information on `"relative_key_query"`, please refer to *Method 4* in [Improve Transformer Models with Better Relative Position Embeddings (Huang et al.)](https://arxiv.org/abs/2009.13658).
* **cross\_attention\_frequency** (`int`, *optional*, defaults to 2) — The frequency of adding cross-attention to the Transformer layers.
* **encoder\_hidden\_size** (`int`, *optional*, defaults to 1408) — The hidden size of the hidden states for cross-attention.
This is the configuration class to store the configuration of a [Blip2QFormerModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2QFormerModel). It is used to instantiate a BLIP-2 Querying Transformer (Q-Former) model according to the specified arguments, defining the model architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of the BLIP-2 [Salesforce/blip2-opt-2.7b](https://huggingface.co/Salesforce/blip2-opt-2.7b) architecture. Configuration objects inherit from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) and can be used to control the model outputs. Read the documentation from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) for more information.
Note that [Blip2QFormerModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2QFormerModel) is very similar to [BertLMHeadModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/bert#transformers.BertLMHeadModel) with interleaved cross-attention.
Examples:
Copied
```
>>> from transformers import Blip2QFormerConfig, Blip2QFormerModel
>>> # Initializing a BLIP-2 Salesforce/blip2-opt-2.7b style configuration
>>> configuration = Blip2QFormerConfig()
>>> # Initializing a model (with random weights) from the Salesforce/blip2-opt-2.7b style configuration
>>> model = Blip2QFormerModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
### Blip2Processor
#### class transformers.Blip2Processor
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/processing_blip_2.py#L27)
( image\_processortokenizer )
Parameters
* **image\_processor** (`BlipImageProcessor`) — An instance of [BlipImageProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip#transformers.BlipImageProcessor). The image processor is a required input.
* **tokenizer** (`AutoTokenizer`) — An instance of \[‘PreTrainedTokenizer\`]. The tokenizer is a required input.
Constructs a BLIP-2 processor which wraps a BLIP image processor and an OPT/T5 tokenizer into a single processor.
[BlipProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip#transformers.BlipProcessor) offers all the functionalities of [BlipImageProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip#transformers.BlipImageProcessor) and [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See the docstring of `__call__()` and [decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip#transformers.BlipProcessor.decode) for more information.
**batch\_decode**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/processing_blip_2.py#L134)
( \*args\*\*kwargs )
This method forwards all its arguments to PreTrainedTokenizer’s [batch\_decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/speecht5#transformers.SpeechT5Tokenizer.batch_decode). Please refer to the docstring of this method for more information.
**decode**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/processing_blip_2.py#L142)
( \*args\*\*kwargs )
This method forwards all its arguments to PreTrainedTokenizer’s [decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/speecht5#transformers.SpeechT5Tokenizer.decode). Please refer to the docstring of this method for more information.
### Blip2VisionModel
#### class transformers.Blip2VisionModel
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L511)
( config: Blip2VisionConfig )
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L526)
( pixel\_values: typing.Optional\[torch.FloatTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.BaseModelOutputWithPooling](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPooling) or `tuple(torch.FloatTensor)`
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`) — Pixel values. Pixel values can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
[transformers.modeling\_outputs.BaseModelOutputWithPooling](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPooling) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.BaseModelOutputWithPooling](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.BaseModelOutputWithPooling) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration (``) and inputs.
* **last\_hidden\_state** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`) — Sequence of hidden-states at the output of the last layer of the model.
* **pooler\_output** (`torch.FloatTensor` of shape `(batch_size, hidden_size)`) — Last layer hidden-state of the first token of the sequence (classification token) after further processing through the layers used for the auxiliary pretraining task. E.g. for BERT-family of models, this returns the classification token after processing through a linear layer and a tanh activation function. The linear layer weights are trained from the next sentence prediction (classification) objective during pretraining.
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
The [Blip2VisionModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2VisionModel) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
### Blip2QFormerModel
#### class transformers.Blip2QFormerModel
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1006)
( config: Blip2QFormerConfig )
Querying Transformer (Q-Former), used in BLIP-2.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1081)
( query\_embeds: FloatTensorattention\_mask: typing.Optional\[torch.FloatTensor] = Nonehead\_mask: typing.Optional\[torch.FloatTensor] = Noneencoder\_hidden\_states: typing.Optional\[torch.FloatTensor] = Noneencoder\_attention\_mask: typing.Optional\[torch.FloatTensor] = Nonepast\_key\_values: typing.Optional\[typing.Tuple\[typing.Tuple\[torch.FloatTensor]]] = Noneuse\_cache: typing.Optional\[bool] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None )
encoder\_hidden\_states (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, `optional`): Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if the model is configured as a decoder. encoder\_attention\_mask (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, `optional`): Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**. past\_key\_values (`tuple(tuple(torch.FloatTensor))` of length `config.n_layers` with each tuple having 4 tensors of: shape `(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`): Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding. If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that don’t have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `decoder_input_ids` of shape `(batch_size, sequence_length)`. use\_cache (`bool`, `optional`): If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see `past_key_values`).
### Blip2Model
#### class transformers.Blip2Model
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1202)
( config: Blip2Config )
Parameters
* **config** ([Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
BLIP-2 Model for generating text and image features. The model consists of a vision encoder, Querying Transformer (Q-Former) and a language model.
This model inherits from [PreTrainedModel](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel). Check the superclass documentation for the generic methods the library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads etc.)
This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1425)
( pixel\_values: FloatTensorinput\_ids: FloatTensorattention\_mask: typing.Optional\[torch.LongTensor] = Nonedecoder\_input\_ids: typing.Optional\[torch.LongTensor] = Nonedecoder\_attention\_mask: typing.Optional\[torch.LongTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonelabels: typing.Optional\[torch.LongTensor] = Nonereturn\_dict: typing.Optional\[bool] = None ) → `transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or `tuple(torch.FloatTensor)`
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`) — Pixel values. Pixel values can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of input sequence tokens in the vocabulary of the language model. Input tokens can optionally be provided to serve as text prompt, which the language model can continue.
Indices can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **attention\_mask** (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **decoder\_input\_ids** (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Indices of decoder input sequence tokens in the vocabulary of the language model. Only relevant in case an encoder-decoder language model (like T5) is used.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details. [What are decoder input IDs?](https://huggingface.co/docs/transformers/glossary#decoder-input-ids)
* **decoder\_attention\_mask** (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default.
Only relevant in case an encoder-decoder language model (like T5) is used.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
`transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or `tuple(torch.FloatTensor)`
A `transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration (``) and inputs.
* **loss** (`torch.FloatTensor`, *optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`) — Language modeling loss from the language model.
* **logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) — Prediction scores of the language modeling head of the language model.
* **vision\_outputs** (`BaseModelOutputWithPooling`) — Outputs of the vision encoder.
* **qformer\_outputs** (`BaseModelOutputWithPoolingAndCrossAttentions`) — Outputs of the Q-Former (Querying Transformer).
* **language\_model\_outputs** (`CausalLMOutputWithPast` or `Seq2SeqLMOutput`) — Outputs of the language model.
The [Blip2Model](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Model) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> from PIL import Image
>>> import requests
>>> from transformers import Blip2Processor, Blip2Model
>>> import torch
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> processor = Blip2Processor.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> model = Blip2Model.from_pretrained("Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16)
>>> model.to(device)
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> prompt = "Question: how many cats are there? Answer:"
>>> inputs = processor(images=image, text=prompt, return_tensors="pt").to(device, torch.float16)
>>> outputs = model(**inputs)
```
**get\_text\_features**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1252)
( input\_ids: typing.Optional\[torch.Tensor] = Noneattention\_mask: typing.Optional\[torch.Tensor] = Nonedecoder\_input\_ids: typing.Optional\[torch.Tensor] = Nonedecoder\_attention\_mask: typing.Optional\[torch.Tensor] = Nonelabels: typing.Optional\[torch.Tensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → text\_outputs (`CausalLMOutputWithPast`, or `tuple(torch.FloatTensor)` if `return_dict=False`)
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide it. Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details. [What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **attention\_mask** (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**. [What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **decoder\_input\_ids** (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Indices of decoder input sequence tokens in the vocabulary.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are decoder input IDs?](https://huggingface.co/docs/transformers/glossary#decoder-input-ids)
T5 uses the `pad_token_id` as the starting token for `decoder_input_ids` generation. If `past_key_values` is used, optionally only the last `decoder_input_ids` have to be input (see `past_key_values`).
To know more on how to prepare `decoder_input_ids` for pretraining take a look at [T5 Training](https://huggingface.co/docs/transformers/model_doc/t5#training).
* **decoder\_attention\_mask** (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
text\_outputs (`CausalLMOutputWithPast`, or `tuple(torch.FloatTensor)` if `return_dict=False`)
The language model outputs. If `return_dict=True`, the output is a `CausalLMOutputWithPast` that contains the language model logits, the past key values and the hidden states if `output_hidden_states=True`.
The [Blip2Model](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Model) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> import torch
>>> from transformers import AutoTokenizer, Blip2Model
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> model = Blip2Model.from_pretrained("Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16)
>>> model.to(device)
>>> tokenizer = AutoTokenizer.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> inputs = tokenizer(["a photo of a cat", "a photo of a dog"], padding=True, return_tensors="pt").to(device)
>>> text_features = model.get_text_features(**inputs)
```
**get\_image\_features**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1315)
( pixel\_values: typing.Optional\[torch.FloatTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → vision\_outputs (`BaseModelOutputWithPooling` or tuple of `torch.FloatTensor`)
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`) — Pixel values. Pixel values can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
vision\_outputs (`BaseModelOutputWithPooling` or tuple of `torch.FloatTensor`)
The vision model outputs. If `return_dict=True`, the output is a `BaseModelOutputWithPooling` that contains the image features, the pooled image features and the hidden states if `output_hidden_states=True`.
The [Blip2Model](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Model) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> import torch
>>> from PIL import Image
>>> import requests
>>> from transformers import AutoProcessor, Blip2Model
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> model = Blip2Model.from_pretrained("Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16)
>>> model.to(device)
>>> processor = AutoProcessor.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> inputs = processor(images=image, return_tensors="pt").to(device, torch.float16)
>>> image_outputs = model.get_image_features(**inputs)
```
**get\_qformer\_features**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1363)
( pixel\_values: typing.Optional\[torch.FloatTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → vision\_outputs (`BaseModelOutputWithPooling` or tuple of `torch.FloatTensor`)
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`) — Pixel values. Pixel values can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of input sequence tokens in the vocabulary of the language model. Input tokens can optionally be provided to serve as text prompt, which the language model can continue.
Indices can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **attention\_mask** (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **decoder\_input\_ids** (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Indices of decoder input sequence tokens in the vocabulary of the language model. Only relevant in case an encoder-decoder language model (like T5) is used.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details. [What are decoder input IDs?](https://huggingface.co/docs/transformers/glossary#decoder-input-ids)
* **decoder\_attention\_mask** (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default.
Only relevant in case an encoder-decoder language model (like T5) is used.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
vision\_outputs (`BaseModelOutputWithPooling` or tuple of `torch.FloatTensor`)
The vision model outputs. If `return_dict=True`, the output is a `BaseModelOutputWithPooling` that contains the image features, the pooled image features and the hidden states if `output_hidden_states=True`.
The [Blip2Model](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Model) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Copied
```
>>> import torch
>>> from PIL import Image
>>> import requests
>>> from transformers import Blip2Processor, Blip2Model
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> processor = Blip2Processor.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> model = Blip2Model.from_pretrained("Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16)
>>> model.to(device)
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> inputs = processor(images=image, return_tensors="pt").to(device, torch.float16)
>>> qformer_outputs = model.get_qformer_features(**inputs)
```
### Blip2ForConditionalGeneration
#### class transformers.Blip2ForConditionalGeneration
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1568)
( config: Blip2Config )
Parameters
* **config** ([Blip2Config](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Config)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
BLIP-2 Model for generating text given an image and an optional text prompt. The model consists of a vision encoder, Querying Transformer (Q-Former) and a language model.
One can optionally pass `input_ids` to the model, which serve as a text prompt, to make the language model continue the prompt. Otherwise, the language model starts generating text from the \[BOS] (beginning-of-sequence) token.
Note that Flan-T5 checkpoints cannot be cast to float16. They are pre-trained using bfloat16.
This model inherits from [PreTrainedModel](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel). Check the superclass documentation for the generic methods the library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads etc.)
This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1638)
( pixel\_values: FloatTensorinput\_ids: FloatTensorattention\_mask: typing.Optional\[torch.LongTensor] = Nonedecoder\_input\_ids: typing.Optional\[torch.LongTensor] = Nonedecoder\_attention\_mask: typing.Optional\[torch.LongTensor] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonelabels: typing.Optional\[torch.LongTensor] = Nonereturn\_dict: typing.Optional\[bool] = None ) → `transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or `tuple(torch.FloatTensor)`
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`) — Pixel values. Pixel values can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Indices of input sequence tokens in the vocabulary of the language model. Input tokens can optionally be provided to serve as text prompt, which the language model can continue.
Indices can be obtained using [Blip2Processor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2Processor). See `Blip2Processor.__call__()` for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **attention\_mask** (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **decoder\_input\_ids** (`torch.LongTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Indices of decoder input sequence tokens in the vocabulary of the language model. Only relevant in case an encoder-decoder language model (like T5) is used.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details. [What are decoder input IDs?](https://huggingface.co/docs/transformers/glossary#decoder-input-ids)
* **decoder\_attention\_mask** (`torch.BoolTensor` of shape `(batch_size, target_sequence_length)`, *optional*) — Default behavior: generate a tensor that ignores pad tokens in `decoder_input_ids`. Causal mask will also be used by default.
Only relevant in case an encoder-decoder language model (like T5) is used.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
`transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or `tuple(torch.FloatTensor)`
A `transformers.models.blip_2.modeling_blip_2.Blip2ForConditionalGenerationModelOutput` or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration (``) and inputs.
* **loss** (`torch.FloatTensor`, *optional*, returned when `labels` is provided, `torch.FloatTensor` of shape `(1,)`) — Language modeling loss from the language model.
* **logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) — Prediction scores of the language modeling head of the language model.
* **vision\_outputs** (`BaseModelOutputWithPooling`) — Outputs of the vision encoder.
* **qformer\_outputs** (`BaseModelOutputWithPoolingAndCrossAttentions`) — Outputs of the Q-Former (Querying Transformer).
* **language\_model\_outputs** (`CausalLMOutputWithPast` or `Seq2SeqLMOutput`) — Outputs of the language model.
The [Blip2ForConditionalGeneration](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/blip-2#transformers.Blip2ForConditionalGeneration) forward method, overrides the `__call__` special method.
Although the recipe for forward pass needs to be defined within this function, one should call the `Module` instance afterwards instead of this since the former takes care of running the pre and post processing steps while the latter silently ignores them.
Examples:
Image captioning (without providing a text prompt):
Copied
```
>>> from PIL import Image
>>> import requests
>>> from transformers import Blip2Processor, Blip2ForConditionalGeneration
>>> import torch
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> processor = Blip2Processor.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> model = Blip2ForConditionalGeneration.from_pretrained(
... "Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16
... )
>>> model.to(device)
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> inputs = processor(images=image, return_tensors="pt").to(device, torch.float16)
>>> generated_ids = model.generate(**inputs)
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0].strip()
>>> print(generated_text)
two cats laying on a couch
```
Visual question answering (prompt = question):
Copied
```
>>> from PIL import Image
>>> import requests
>>> from transformers import Blip2Processor, Blip2ForConditionalGeneration
>>> import torch
>>> device = "cuda" if torch.cuda.is_available() else "cpu"
>>> processor = Blip2Processor.from_pretrained("Salesforce/blip2-opt-2.7b")
>>> model = Blip2ForConditionalGeneration.from_pretrained(
... "Salesforce/blip2-opt-2.7b", load_in_8bit=True, device_map={"": 0}, torch_dtype=torch.float16
... ) # doctest: +IGNORE_RESULT
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> prompt = "Question: how many cats are there? Answer:"
>>> inputs = processor(images=image, text=prompt, return_tensors="pt").to(device="cuda", dtype=torch.float16)
>>> generated_ids = model.generate(**inputs)
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0].strip()
>>> print(generated_text)
two
```
Note that int8 inference is also supported through [bitsandbytes](https://github.com/TimDettmers/bitsandbytes). This greatly reduces the amount of memory used by the model while maintaining the same performance.
Copied
```
>>> from PIL import Image
>>> import requests
>>> from transformers import Blip2Processor, Blip2ForConditionalGeneration
>>> import torch
>>> processor = Blip2Processor.from_pretrained("Salesforce/blip2-flan-t5-xl")
>>> model = Blip2ForConditionalGeneration.from_pretrained(
... "Salesforce/blip2-flan-t5-xl", load_in_8bit=True, device_map={"": 0}, torch_dtype=torch.bfloat16
... ) # doctest: +IGNORE_RESULT
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> prompt = "Question: how many cats are there? Answer:"
>>> inputs = processor(images=image, text=prompt, return_tensors="pt").to(device="cuda", dtype=torch.bfloat16)
>>> generated_ids = model.generate(**inputs)
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0].strip()
>>> print(generated_text)
two
```
**generate**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/blip_2/modeling_blip_2.py#L1823)
( pixel\_values: FloatTensorinput\_ids: typing.Optional\[torch.LongTensor] = Noneattention\_mask: typing.Optional\[torch.LongTensor] = None\*\*generate\_kwargs ) → captions (list)
Parameters
* **pixel\_values** (`torch.FloatTensor` of shape (batch\_size, num\_channels, height, width)) — Input images to be processed.
* **input\_ids** (`torch.LongTensor` of shape (batch\_size, sequence\_length), *optional*) — The sequence used as a prompt for the generation.
* **attention\_mask** (`torch.LongTensor` of shape (batch\_size, sequence\_length), *optional*) — Mask to avoid performing attention on padding token indices
Returns
captions (list)
A list of strings of length batch\_size \* num\_captions.
Overrides `generate` function to be able to use the model as a conditional generator.