> For the complete documentation index, see [llms.txt](https://boinc-ai.gitbook.io/transformers/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://boinc-ai.gitbook.io/transformers/api/models/multimodal-models/trocr.md).
# TrOCR
## TrOCR
### Overview
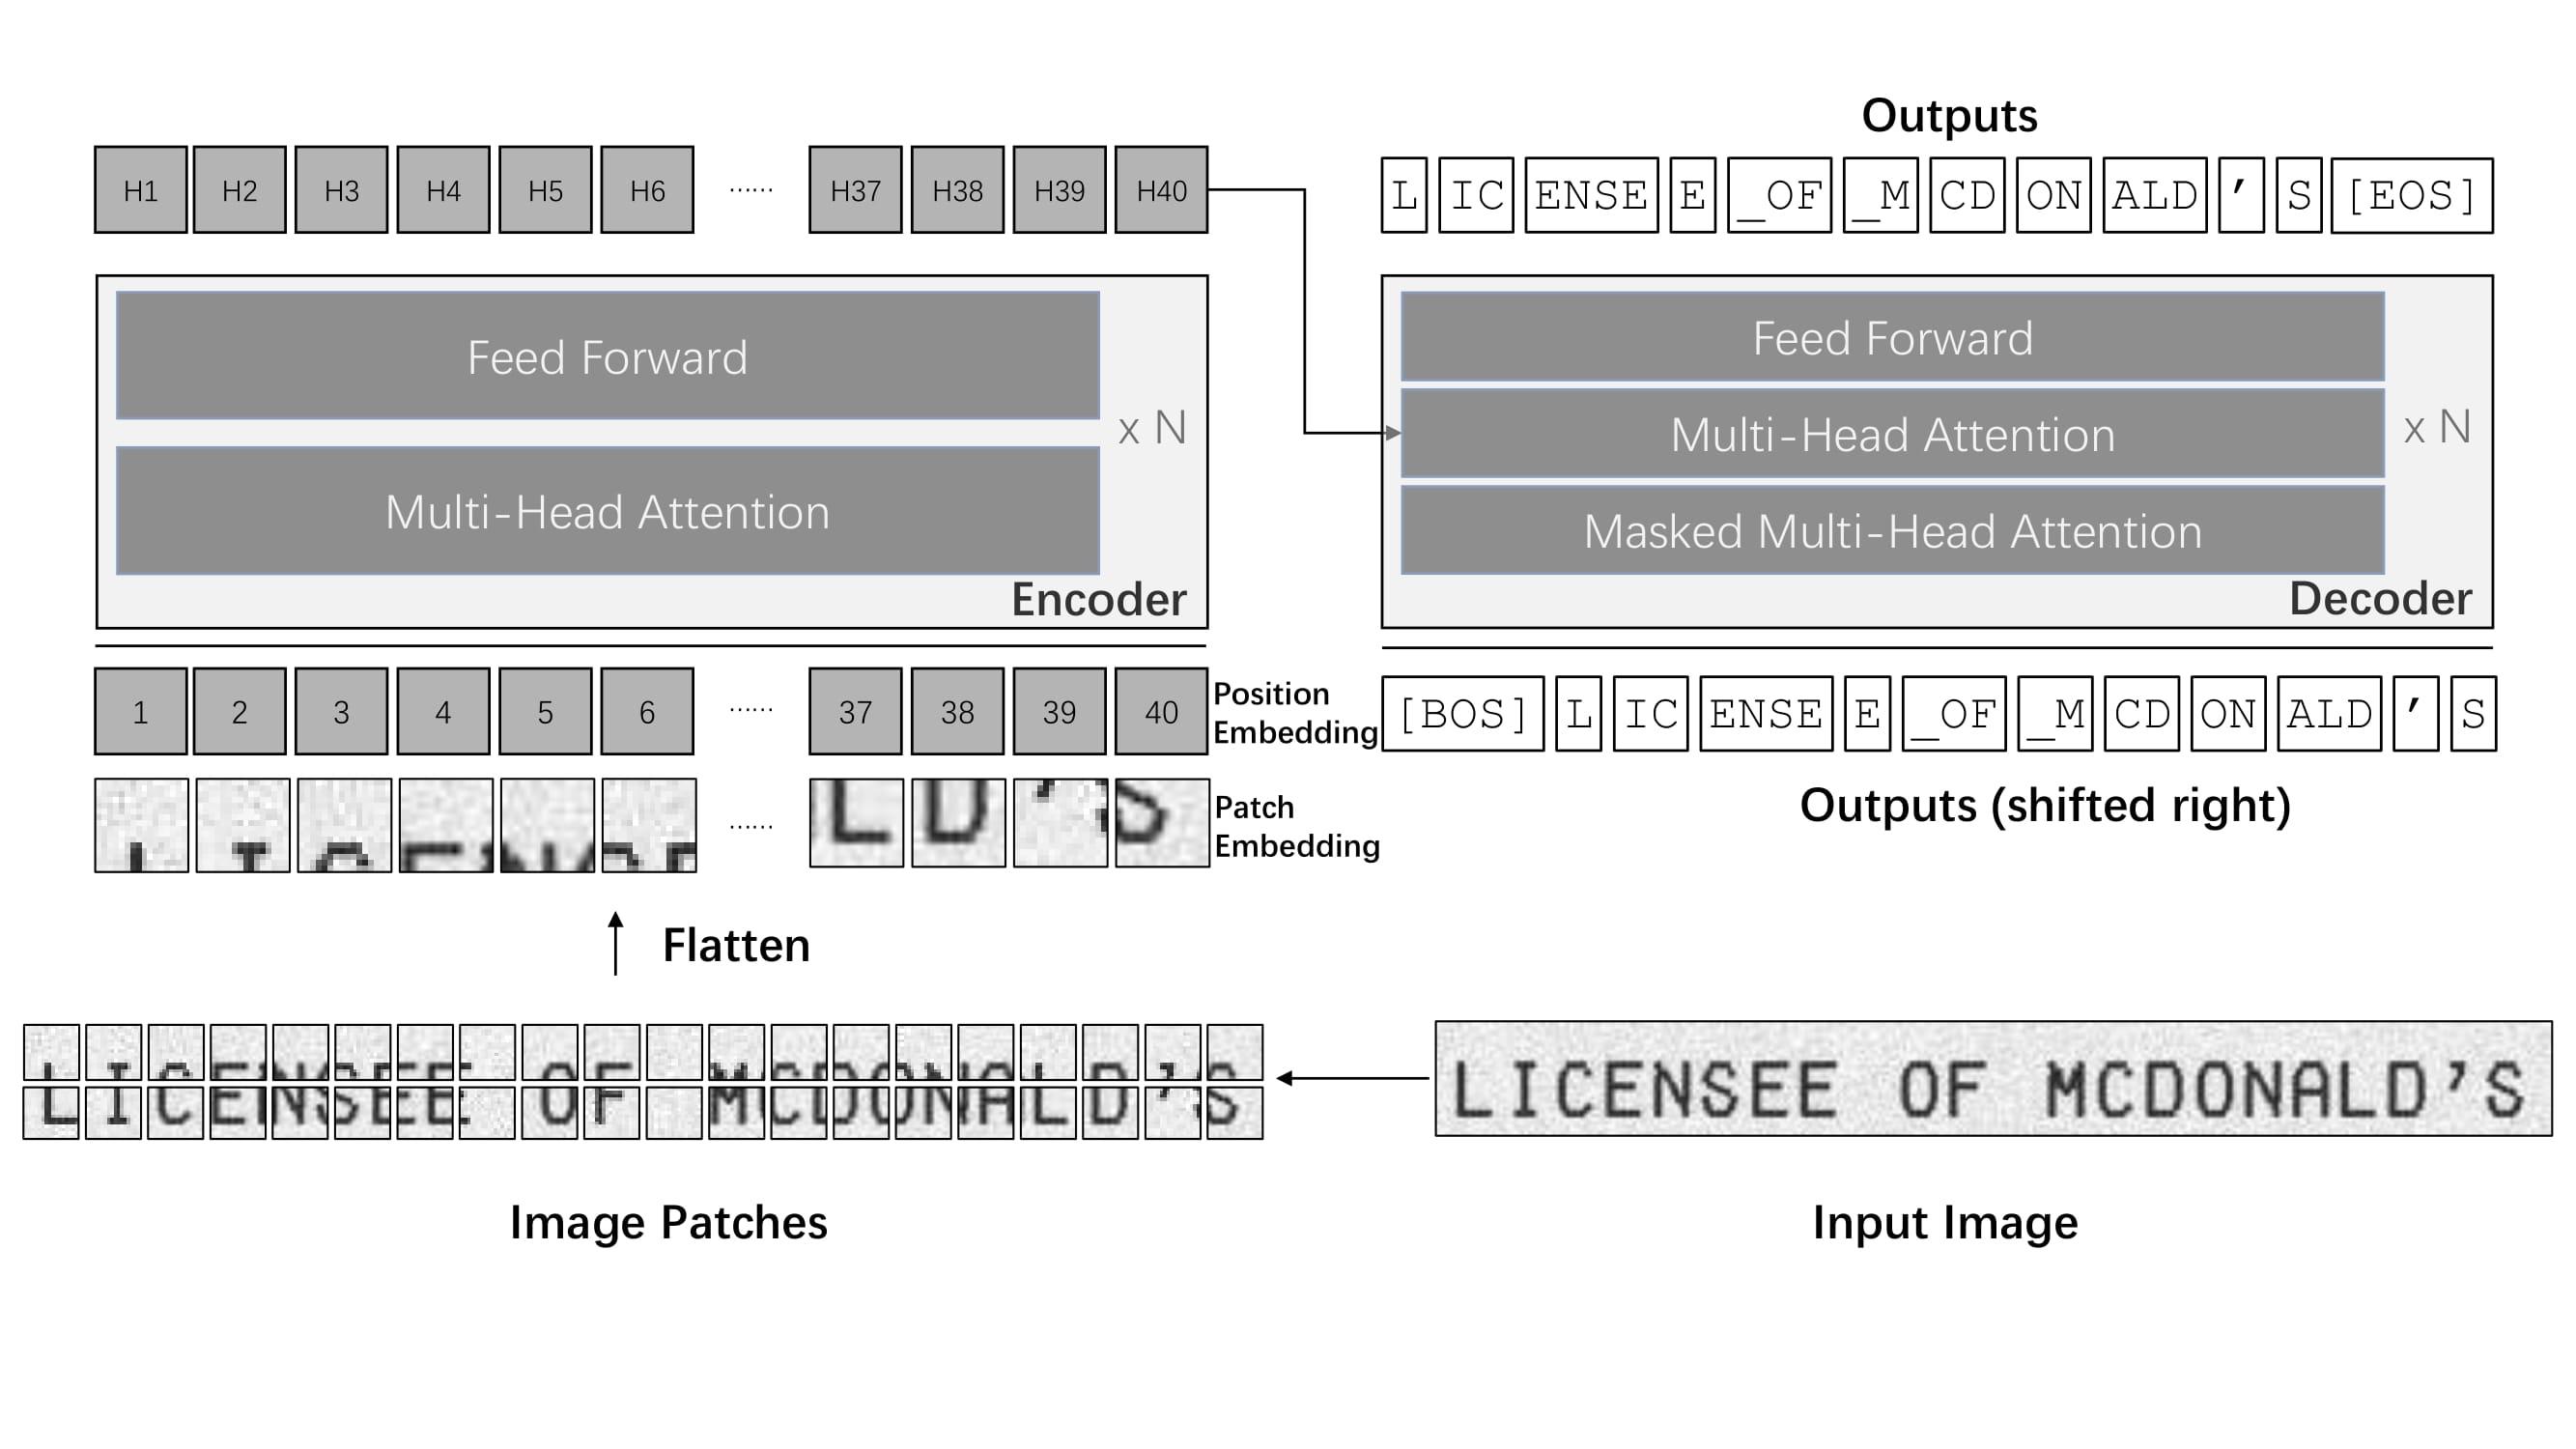
The TrOCR model was proposed in [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei. TrOCR consists of an image Transformer encoder and an autoregressive text Transformer decoder to perform [optical character recognition (OCR)](https://en.wikipedia.org/wiki/Optical_character_recognition).
The abstract from the paper is the following:
*Text recognition is a long-standing research problem for document digitalization. Existing approaches for text recognition are usually built based on CNN for image understanding and RNN for char-level text generation. In addition, another language model is usually needed to improve the overall accuracy as a post-processing step. In this paper, we propose an end-to-end text recognition approach with pre-trained image Transformer and text Transformer models, namely TrOCR, which leverages the Transformer architecture for both image understanding and wordpiece-level text generation. The TrOCR model is simple but effective, and can be pre-trained with large-scale synthetic data and fine-tuned with human-labeled datasets. Experiments show that the TrOCR model outperforms the current state-of-the-art models on both printed and handwritten text recognition tasks.*
TrOCR architecture. Taken from the [original paper](https://arxiv.org/abs/2109.10282).
Please refer to the `VisionEncoderDecoder` class on how to use this model.
This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm/tree/6f60612e7cc86a2a1ae85c47231507a587ab4e01/trocr).
Tips:
* The quickest way to get started with TrOCR is by checking the [tutorial notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/TrOCR), which show how to use the model at inference time as well as fine-tuning on custom data.
* TrOCR is pre-trained in 2 stages before being fine-tuned on downstream datasets. It achieves state-of-the-art results on both printed (e.g. the [SROIE dataset](https://paperswithcode.com/dataset/sroie) and handwritten (e.g. the [IAM Handwriting dataset](https://fki.tic.heia-fr.ch/databases/iam-handwriting-database%3E) text recognition tasks. For more information, see the [official models](https://huggingface.co/models?other=trocr%3E).
* TrOCR is always used within the [VisionEncoderDecoder](https://huggingface.co/docs/transformers/model_doc/vision-encoder-decoder) framework.
### Resources
A list of official BOINC AI and community (indicated by 🌎) resources to help you get started with TrOCR. If you’re interested in submitting a resource to be included here, please feel free to open a Pull Request and we’ll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
Text Classification
* A blog post on [Accelerating Document AI](https://huggingface.co/blog/document-ai) with TrOCR.
* A blog post on how to [Document AI](https://github.com/philschmid/document-ai-transformers) with TrOCR.
* A notebook on how to [finetune TrOCR on IAM Handwriting Database using Seq2SeqTrainer](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Fine_tune_TrOCR_on_IAM_Handwriting_Database_using_Seq2SeqTrainer.ipynb).
* A notebook on [inference with TrOCR](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Inference_with_TrOCR_%2B_Gradio_demo.ipynb) and Gradio demo.
* A notebook on [finetune TrOCR on the IAM Handwriting Database](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Fine_tune_TrOCR_on_IAM_Handwriting_Database_using_native_PyTorch.ipynb) using native PyTorch.
* A notebook on [evaluating TrOCR on the IAM test set](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Evaluating_TrOCR_base_handwritten_on_the_IAM_test_set.ipynb).
Text Generation
* [Casual language modeling](https://huggingface.co/docs/transformers/tasks/language_modeling) task guide.
⚡️ Inference
* An interactive-demo on [TrOCR handwritten character recognition](https://huggingface.co/spaces/nielsr/TrOCR-handwritten).
### Inference
TrOCR’s `VisionEncoderDecoder` model accepts images as input and makes use of [generate()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/text_generation#transformers.GenerationMixin.generate) to autoregressively generate text given the input image.
The \[`ViTImageProcessor`/`DeiTImageProcessor`] class is responsible for preprocessing the input image and \[`RobertaTokenizer`/`XLMRobertaTokenizer`] decodes the generated target tokens to the target string. The [TrOCRProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRProcessor) wraps \[`ViTImageProcessor`/`DeiTImageProcessor`] and \[`RobertaTokenizer`/`XLMRobertaTokenizer`] into a single instance to both extract the input features and decode the predicted token ids.
* Step-by-step Optical Character Recognition (OCR)
Copied
```
>>> from transformers import TrOCRProcessor, VisionEncoderDecoderModel
>>> import requests
>>> from PIL import Image
>>> processor = TrOCRProcessor.from_pretrained("microsoft/trocr-base-handwritten")
>>> model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
>>> # load image from the IAM dataset
>>> url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
>>> pixel_values = processor(image, return_tensors="pt").pixel_values
>>> generated_ids = model.generate(pixel_values)
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
```
See the [model hub](https://huggingface.co/models?filter=trocr) to look for TrOCR checkpoints.
### TrOCRConfig
#### class transformers.TrOCRConfig
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/configuration_trocr.py#L31)
( vocab\_size = 50265d\_model = 1024decoder\_layers = 12decoder\_attention\_heads = 16decoder\_ffn\_dim = 4096activation\_function = 'gelu'max\_position\_embeddings = 512dropout = 0.1attention\_dropout = 0.0activation\_dropout = 0.0decoder\_start\_token\_id = 2init\_std = 0.02decoder\_layerdrop = 0.0use\_cache = Truescale\_embedding = Falseuse\_learned\_position\_embeddings = Truelayernorm\_embedding = Truepad\_token\_id = 1bos\_token\_id = 0eos\_token\_id = 2\*\*kwargs )
Parameters
* **vocab\_size** (`int`, *optional*, defaults to 50265) — Vocabulary size of the TrOCR model. Defines the number of different tokens that can be represented by the `inputs_ids` passed when calling [TrOCRForCausalLM](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRForCausalLM).
* **d\_model** (`int`, *optional*, defaults to 1024) — Dimensionality of the layers and the pooler layer.
* **decoder\_layers** (`int`, *optional*, defaults to 12) — Number of decoder layers.
* **decoder\_attention\_heads** (`int`, *optional*, defaults to 16) — Number of attention heads for each attention layer in the Transformer decoder.
* **decoder\_ffn\_dim** (`int`, *optional*, defaults to 4096) — Dimensionality of the “intermediate” (often named feed-forward) layer in decoder.
* **activation\_function** (`str` or `function`, *optional*, defaults to `"gelu"`) — The non-linear activation function (function or string) in the pooler. If string, `"gelu"`, `"relu"`, `"silu"` and `"gelu_new"` are supported.
* **max\_position\_embeddings** (`int`, *optional*, defaults to 512) — The maximum sequence length that this model might ever be used with. Typically set this to something large just in case (e.g., 512 or 1024 or 2048).
* **dropout** (`float`, *optional*, defaults to 0.1) — The dropout probability for all fully connected layers in the embeddings, and pooler.
* **attention\_dropout** (`float`, *optional*, defaults to 0.0) — The dropout ratio for the attention probabilities.
* **activation\_dropout** (`float`, *optional*, defaults to 0.0) — The dropout ratio for activations inside the fully connected layer.
* **init\_std** (`float`, *optional*, defaults to 0.02) — The standard deviation of the truncated\_normal\_initializer for initializing all weight matrices.
* **decoder\_layerdrop** (`float`, *optional*, defaults to 0.0) — The LayerDrop probability for the decoder. See the \[LayerDrop paper]\(see ) for more details.
* **use\_cache** (`bool`, *optional*, defaults to `True`) — Whether or not the model should return the last key/values attentions (not used by all models).
* **scale\_embedding** (`bool`, *optional*, defaults to `False`) — Whether or not to scale the word embeddings by sqrt(d\_model).
* **use\_learned\_position\_embeddings** (`bool`, *optional*, defaults to `True`) — Whether or not to use learned position embeddings. If not, sinusoidal position embeddings will be used.
* **layernorm\_embedding** (`bool`, *optional*, defaults to `True`) — Whether or not to use a layernorm after the word + position embeddings.
This is the configuration class to store the configuration of a [TrOCRForCausalLM](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRForCausalLM). It is used to instantiate an TrOCR model according to the specified arguments, defining the model architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of the TrOCR [microsoft/trocr-base-handwritten](https://huggingface.co/microsoft/trocr-base-handwritten) architecture.
Configuration objects inherit from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) and can be used to control the model outputs. Read the documentation from [PretrainedConfig](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/configuration#transformers.PretrainedConfig) for more information.
Example:
Copied
```
>>> from transformers import TrOCRConfig, TrOCRForCausalLM
>>> # Initializing a TrOCR-base style configuration
>>> configuration = TrOCRConfig()
>>> # Initializing a model (with random weights) from the TrOCR-base style configuration
>>> model = TrOCRForCausalLM(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
### TrOCRProcessor
#### class transformers.TrOCRProcessor
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/processing_trocr.py#L24)
( image\_processor = Nonetokenizer = None\*\*kwargs )
Parameters
* **image\_processor** (\[`ViTImageProcessor`/`DeiTImageProcessor`]) — An instance of \[`ViTImageProcessor`/`DeiTImageProcessor`]. The image processor is a required input.
* **tokenizer** (\[`RobertaTokenizer`/`XLMRobertaTokenizer`]) — An instance of \[`RobertaTokenizer`/`XLMRobertaTokenizer`]. The tokenizer is a required input.
Constructs a TrOCR processor which wraps a vision image processor and a TrOCR tokenizer into a single processor.
[TrOCRProcessor](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRProcessor) offers all the functionalities of \[`ViTImageProcessor`/`DeiTImageProcessor`] and \[`RobertaTokenizer`/`XLMRobertaTokenizer`]. See the [**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRProcessor.__call__) and [decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRProcessor.decode) for more information.
**\_\_call\_\_**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/processing_trocr.py#L62)
( \*args\*\*kwargs )
When used in normal mode, this method forwards all its arguments to AutoImageProcessor’s `__call__()` and returns its output. If used in the context `as_target_processor()` this method forwards all its arguments to TrOCRTokenizer’s `~TrOCRTokenizer.__call__`. Please refer to the doctsring of the above two methods for more information.
**from\_pretrained**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/processing_utils.py#L167)
( pretrained\_model\_name\_or\_path: typing.Union\[str, os.PathLike]cache\_dir: typing.Union\[str, os.PathLike, NoneType] = Noneforce\_download: bool = Falselocal\_files\_only: bool = Falsetoken: typing.Union\[bool, str, NoneType] = Nonerevision: str = 'main'\*\*kwargs )
Parameters
* **pretrained\_model\_name\_or\_path** (`str` or `os.PathLike`) — This can be either:
* a string, the *model id* of a pretrained feature\_extractor hosted inside a model repo on huggingface.co. Valid model ids can be located at the root-level, like `bert-base-uncased`, or namespaced under a user or organization name, like `dbmdz/bert-base-german-cased`.
* a path to a *directory* containing a feature extractor file saved using the [save\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/feature_extractor#transformers.FeatureExtractionMixin.save_pretrained) method, e.g., `./my_model_directory/`.
* a path or url to a saved feature extractor JSON *file*, e.g., `./my_model_directory/preprocessor_config.json`. \*\*kwargs — Additional keyword arguments passed along to both [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/feature_extractor#transformers.FeatureExtractionMixin.from_pretrained) and `~tokenization_utils_base.PreTrainedTokenizer.from_pretrained`.
Instantiate a processor associated with a pretrained model.
This class method is simply calling the feature extractor [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/feature_extractor#transformers.FeatureExtractionMixin.from_pretrained), image processor [ImageProcessingMixin](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/image_processor#transformers.ImageProcessingMixin) and the tokenizer `~tokenization_utils_base.PreTrainedTokenizer.from_pretrained` methods. Please refer to the docstrings of the methods above for more information.
**save\_pretrained**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/processing_utils.py#L93)
( save\_directorypush\_to\_hub: bool = False\*\*kwargs )
Parameters
* **save\_directory** (`str` or `os.PathLike`) — Directory where the feature extractor JSON file and the tokenizer files will be saved (directory will be created if it does not exist).
* **push\_to\_hub** (`bool`, *optional*, defaults to `False`) — Whether or not to push your model to the BOINC AI model hub after saving it. You can specify the repository you want to push to with `repo_id` (will default to the name of `save_directory` in your namespace).
* **kwargs** (`Dict[str, Any]`, *optional*) — Additional key word arguments passed along to the [push\_to\_hub()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/processors#transformers.ProcessorMixin.push_to_hub) method.
Saves the attributes of this processor (feature extractor, tokenizer…) in the specified directory so that it can be reloaded using the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/nougat#transformers.NougatProcessor.from_pretrained) method.
This class method is simply calling [save\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/feature_extractor#transformers.FeatureExtractionMixin.save_pretrained) and [save\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/internal/tokenization_utils#transformers.PreTrainedTokenizerBase.save_pretrained). Please refer to the docstrings of the methods above for more information.
**batch\_decode**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/processing_trocr.py#L95)
( \*args\*\*kwargs )
This method forwards all its arguments to TrOCRTokenizer’s [batch\_decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/speecht5#transformers.SpeechT5Tokenizer.batch_decode). Please refer to the docstring of this method for more information.
**decode**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/processing_trocr.py#L102)
( \*args\*\*kwargs )
This method forwards all its arguments to TrOCRTokenizer’s [decode()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/speecht5#transformers.SpeechT5Tokenizer.decode). Please refer to the docstring of this method for more information.
### TrOCRForCausalLM
#### class transformers.TrOCRForCausalLM
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/modeling_trocr.py#L790)
( config )
Parameters
* **config** ([TrOCRConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRConfig)) — Model configuration class with all the parameters of the model. Initializing with a config file does not load the weights associated with the model, only the configuration. Check out the [from\_pretrained()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel.from_pretrained) method to load the model weights.
The TrOCR Decoder with a language modeling head. Can be used as the decoder part of [EncoderDecoderModel](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/encoder-decoder#transformers.EncoderDecoderModel) and `VisionEncoderDecoder`. This model inherits from [PreTrainedModel](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/model#transformers.PreTrainedModel). Check the superclass documentation for the generic methods the library implements for all its model (such as downloading or saving, resizing the input embeddings, pruning heads etc.)
This model is also a PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) subclass. Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general usage and behavior.
**forward**
[\](https://github.com/huggingface/transformers/blob/v4.34.1/src/transformers/models/trocr/modeling_trocr.py#L823)
( input\_ids: typing.Optional\[torch.LongTensor] = Noneattention\_mask: typing.Optional\[torch.Tensor] = Noneencoder\_hidden\_states: typing.Optional\[torch.FloatTensor] = Noneencoder\_attention\_mask: typing.Optional\[torch.LongTensor] = Nonehead\_mask: typing.Optional\[torch.Tensor] = Nonecross\_attn\_head\_mask: typing.Optional\[torch.Tensor] = Nonepast\_key\_values: typing.Optional\[typing.Tuple\[typing.Tuple\[torch.FloatTensor]]] = Noneinputs\_embeds: typing.Optional\[torch.FloatTensor] = Nonelabels: typing.Optional\[torch.LongTensor] = Noneuse\_cache: typing.Optional\[bool] = Noneoutput\_attentions: typing.Optional\[bool] = Noneoutput\_hidden\_states: typing.Optional\[bool] = Nonereturn\_dict: typing.Optional\[bool] = None ) → [transformers.modeling\_outputs.CausalLMOutputWithCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.CausalLMOutputWithCrossAttentions) or `tuple(torch.FloatTensor)`
Parameters
* **input\_ids** (`torch.LongTensor` of shape `(batch_size, sequence_length)`) — Indices of input sequence tokens in the vocabulary. Padding will be ignored by default should you provide it.
Indices can be obtained using [AutoTokenizer](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/auto#transformers.AutoTokenizer). See [PreTrainedTokenizer.encode()](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast.encode) and [PreTrainedTokenizer.**call**()](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/vits#transformers.VitsTokenizer.__call__) for details.
[What are input IDs?](https://huggingface.co/docs/transformers/glossary#input-ids)
* **attention\_mask** (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**.
[What are attention masks?](https://huggingface.co/docs/transformers/glossary#attention-mask)
* **encoder\_hidden\_states** (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`, *optional*) — Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if the model is configured as a decoder.
* **encoder\_attention\_mask** (`torch.FloatTensor` of shape `(batch_size, sequence_length)`, *optional*) — Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in the cross-attention if the model is configured as a decoder. Mask values selected in `[0, 1]`:
* **head\_mask** (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*) — Mask to nullify selected heads of the attention modules. Mask values selected in `[0, 1]`:
* 1 indicates the head is **not masked**,
* 0 indicates the head is **masked**.
* **cross\_attn\_head\_mask** (`torch.Tensor` of shape `(decoder_layers, decoder_attention_heads)`, *optional*) — Mask to nullify selected heads of the cross-attention modules. Mask values selected in `[0, 1]`:
* 1 indicates the head is **not masked**,
* 0 indicates the head is **masked**.
* **past\_key\_values** (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`) — Tuple of `tuple(torch.FloatTensor)` of length `config.n_layers`, with each tuple having 2 tensors of shape `(batch_size, num_heads, sequence_length, embed_size_per_head)`) and 2 additional tensors of shape `(batch_size, num_heads, encoder_sequence_length, embed_size_per_head)`. The two additional tensors are only required when the model is used as a decoder in a Sequence to Sequence model.
Contains pre-computed hidden-states (key and values in the self-attention blocks and in the cross-attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
If `past_key_values` are used, the user can optionally input only the last `decoder_input_ids` (those that don’t have their past key value states given to this model) of shape `(batch_size, 1)` instead of all `decoder_input_ids` of shape `(batch_size, sequence_length)`.
* **labels** (`torch.LongTensor` of shape `(batch_size, sequence_length)`, *optional*) — Labels for computing the masked language modeling loss. Indices should either be in `[0, ..., config.vocab_size]` or -100 (see `input_ids` docstring). Tokens with indices set to `-100` are ignored (masked), the loss is only computed for the tokens with labels in `[0, ..., config.vocab_size]`.
* **use\_cache** (`bool`, *optional*) — If set to `True`, `past_key_values` key value states are returned and can be used to speed up decoding (see `past_key_values`).
* 1 for tokens that are **not masked**,
* 0 for tokens that are **masked**.
* **output\_attentions** (`bool`, *optional*) — Whether or not to return the attentions tensors of all attention layers. See `attentions` under returned tensors for more detail.
* **output\_hidden\_states** (`bool`, *optional*) — Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors for more detail.
* **return\_dict** (`bool`, *optional*) — Whether or not to return a [ModelOutput](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.utils.ModelOutput) instead of a plain tuple.
Returns
[transformers.modeling\_outputs.CausalLMOutputWithCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.CausalLMOutputWithCrossAttentions) or `tuple(torch.FloatTensor)`
A [transformers.modeling\_outputs.CausalLMOutputWithCrossAttentions](https://huggingface.co/docs/transformers/v4.34.1/en/main_classes/output#transformers.modeling_outputs.CausalLMOutputWithCrossAttentions) or a tuple of `torch.FloatTensor` (if `return_dict=False` is passed or when `config.return_dict=False`) comprising various elements depending on the configuration ([TrOCRConfig](https://huggingface.co/docs/transformers/v4.34.1/en/model_doc/trocr#transformers.TrOCRConfig)) and inputs.
* **loss** (`torch.FloatTensor` of shape `(1,)`, *optional*, returned when `labels` is provided) — Language modeling loss (for next-token prediction).
* **logits** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) — Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
* **hidden\_states** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_hidden_states=True` is passed or when `config.output_hidden_states=True`) — Tuple of `torch.FloatTensor` (one for the output of the embeddings, if the model has an embedding layer, + one for the output of each layer) of shape `(batch_size, sequence_length, hidden_size)`.
Hidden-states of the model at the output of each layer plus the optional initial embedding outputs.
* **attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
* **cross\_attentions** (`tuple(torch.FloatTensor)`, *optional*, returned when `output_attentions=True` is passed or when `config.output_attentions=True`) — Tuple of `torch.FloatTensor` (one for each layer) of shape `(batch_size, num_heads, sequence_length, sequence_length)`.
Cross attentions weights after the attention softmax, used to compute the weighted average in the cross-attention heads.
* **past\_key\_values** (`tuple(tuple(torch.FloatTensor))`, *optional*, returned when `use_cache=True` is passed or when `config.use_cache=True`) — Tuple of `torch.FloatTensor` tuples of length `config.n_layers`, with each tuple containing the cached key, value states of the self-attention and the cross-attention layers if model is used in encoder-decoder setting. Only relevant if `config.is_decoder = True`.
Contains pre-computed hidden-states (key and values in the attention blocks) that can be used (see `past_key_values` input) to speed up sequential decoding.
Example:
Copied
```
>>> from transformers import (
... TrOCRConfig,
... TrOCRProcessor,
... TrOCRForCausalLM,
... ViTConfig,
... ViTModel,
... VisionEncoderDecoderModel,
... )
>>> import requests
>>> from PIL import Image
>>> # TrOCR is a decoder model and should be used within a VisionEncoderDecoderModel
>>> # init vision2text model with random weights
>>> encoder = ViTModel(ViTConfig())
>>> decoder = TrOCRForCausalLM(TrOCRConfig())
>>> model = VisionEncoderDecoderModel(encoder=encoder, decoder=decoder)
>>> # If you want to start from the pretrained model, load the checkpoint with `VisionEncoderDecoderModel`
>>> processor = TrOCRProcessor.from_pretrained("microsoft/trocr-base-handwritten")
>>> model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
>>> # load image from the IAM dataset
>>> url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
>>> pixel_values = processor(image, return_tensors="pt").pixel_values
>>> text = "industry, ' Mr. Brown commented icily. ' Let us have a"
>>> # training
>>> model.config.decoder_start_token_id = processor.tokenizer.cls_token_id
>>> model.config.pad_token_id = processor.tokenizer.pad_token_id
>>> model.config.vocab_size = model.config.decoder.vocab_size
>>> labels = processor.tokenizer(text, return_tensors="pt").input_ids
>>> outputs = model(pixel_values, labels=labels)
>>> loss = outputs.loss
>>> round(loss.item(), 2)
5.30
>>> # inference
>>> generated_ids = model.generate(pixel_values)
>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
>>> generated_text
'industry, " Mr. Brown commented icily. " Let us have a'
```